S01E01 · Mechanics Behind Generative AI: MEGA lesson
MEGA’s written lesson introduces how generative AI works, including tokenization, next-token prediction, non-determinism, confabulation, and reasoning. It also surveys model interactions and ways to steer outputs.
textMEGA · hq.mega.dev · Saved Nov 19, 2026
mega course, tokenization, llm reasoning, llm hallucinations, uncertainty calibration
Written lesson S01E01 of the MEGA.dev course, by MEGA. Agenda: Introduction · Mechanics · Limitations · Providers · Interactions · Steering. Its lesson video is presented by Theo Browne and saved separately. (MEGA Student HQ, needs a login.)
S01E01 · Mechanics Behind Generative AI
Generative AI is changing how we work. Many of us are working faster, tackling more complex problems, or improving the quality and security of our products.
But as agents take over more and more of the work we've done for years, some of us have started to question the future of programming. We may wonder whether our jobs will still exist a few months from now. Along the way, this shift can wear away the satisfaction, the sense of purpose and even the joy we once found in our work.
MEGA.dev is a story about all of this. And I’m inviting you to join us for the next 4 weeks to learn about generative AI. Together with Theo, Angie, Kent and John, we’ll look at what it means to be a MEGA Developer and how to become one.
Outline
- Introduction: generative AI, harnesses, configuration, agentic tooling, custom tools
- Mechanics: instructions, completion, tokenization, prediction, attention, instruction following
- Limitations: illusions, confabulation, base knowledge, knowledge cutoff, context windows, output limits
- Providers: models, capabilities, features, settings, pricing, specialization, model mixing
- Interactions: text generation, structured outputs, function calling, native tools, external tools
- Steering: generalization, associations, self-querying, latent space, J-space, reasoning
Before we start: the first two lessons aim to give you a broad perspective on many topics. Don't expect to understand everything in a day or two. Just go through the videos, texts, examples and exercises, and play with whatever catches your attention.
Things worth knowing about LLMs
Working with Large Language Models (LLMs) is easy: all we need to do is send a message. But if we look closer, we'll find there are things we can do to get better results, and that can be pushed far beyond direct interaction. On the internet, we can find setups, tools and workflows, but often they have to be adjusted to our projects and our preferences. Then it's useful to have a general understanding of what's going on under the hood.
Large language models are typically neural networks trained on large amounts of text to generate content by predicting what comes next. We can think of them as functions that take an input (a prompt) and return an output (a completion). But today, models such as GPT-6 are more like systems that can process multimodal input, generate multimodal output and “reason” about what they do.
The LLMs we work with are often available through platforms and tools such as ChatGPT, Cursor, Claude Code, or Gemini, but we can also interact with them through an API. No matter which model or tools we use, certain traits and mechanisms are always present, even if they aren't visible on the surface.
Below we have an overview of the most important things we need to get a brief understanding of before moving further.
Tokenization: LLMs work with numbers, so any data we want to process has to be encoded as numbers and then decoded back. This led to the idea of tokenizers, which assign identifiers to chunks of text. The chunks are chosen through a process that optimizes both the number of chunks in a dictionary and their size. That's all you need to know for now, but if you're interested, Let's build the GPT Tokenizer is one of the best resources on the topic.
Paste a sentence into Tokenization round trip and look at each token and its ID. Then type the same sentence with an emoji, or in a different language, and watch the token count grow.
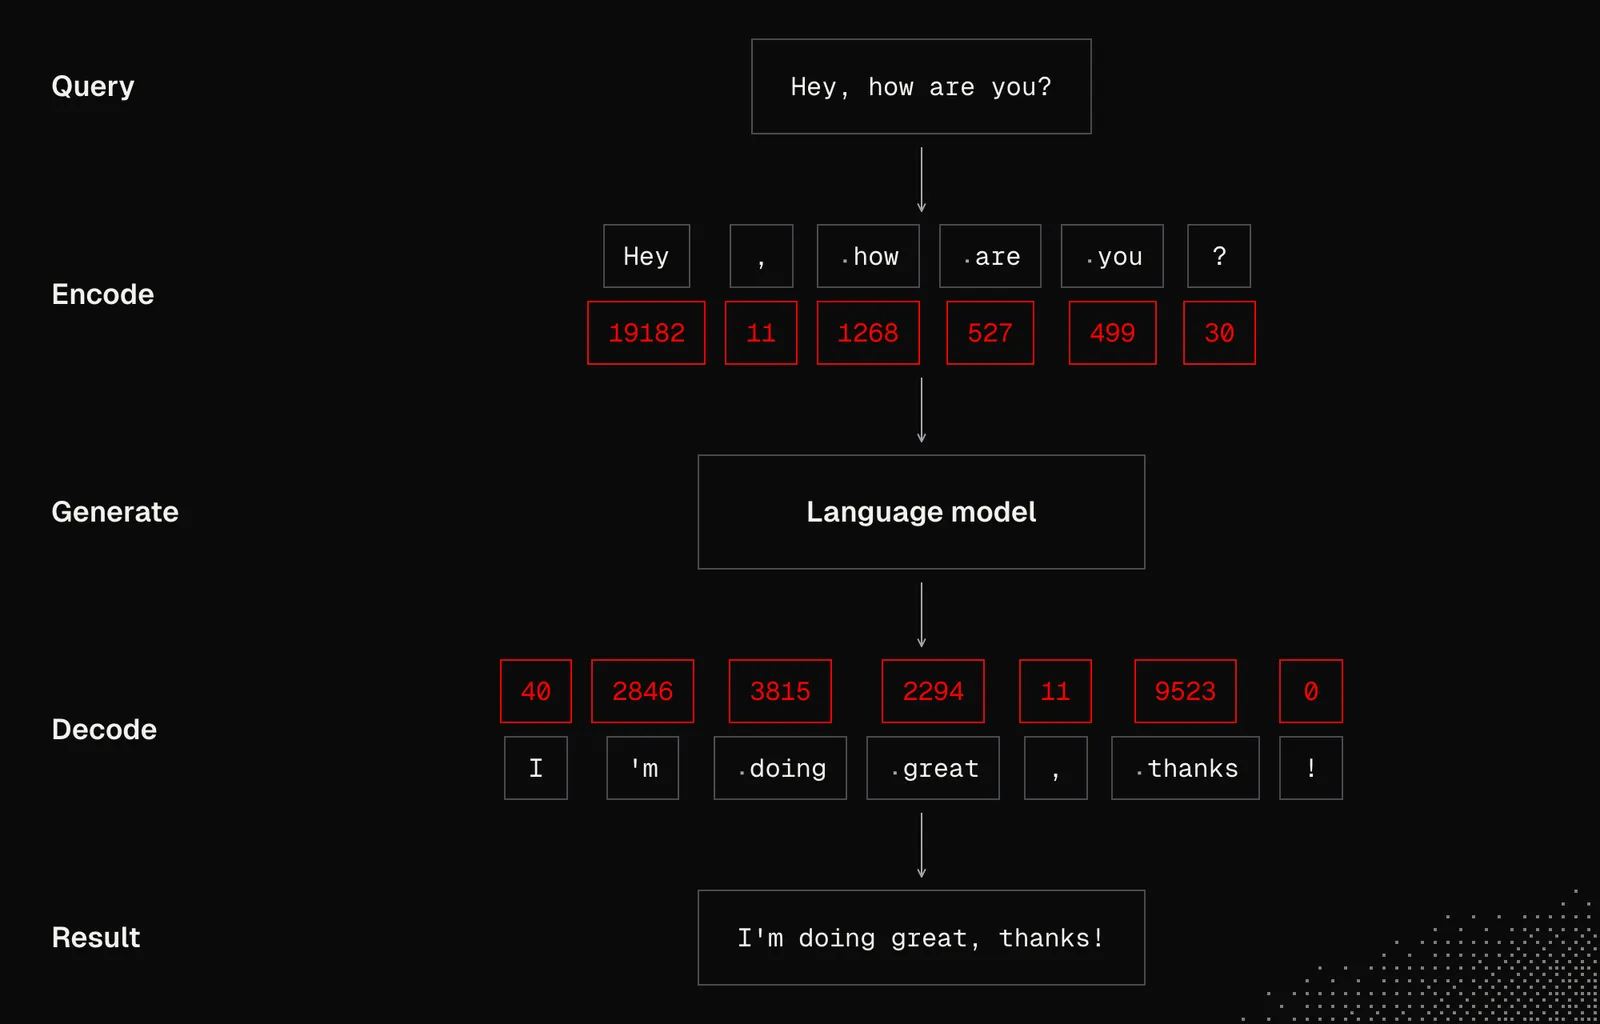
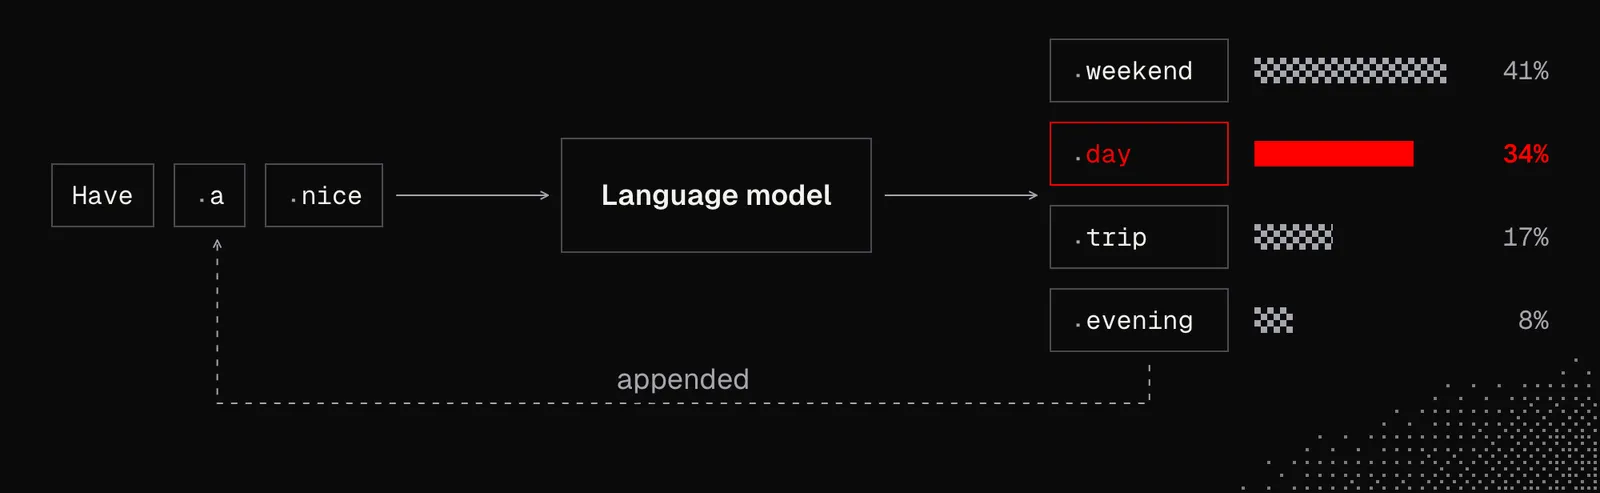
Predicting the Next Token: An LLM generates content token by token, “predicting” what comes next based on what came before. It repeats this process until it selects a special "end token". The tricky part is that no one can tell exactly what the output will be or why it selects particular tokens. Also, once a token is chosen, there's no way to remove it, so one poor decision may negatively affect subsequent tokens, and that effect adds up. But we know a lot about the mechanics behind it, and What Is ChatGPT Doing … and Why Does It Work? is an older but still accurate write-up on the topic.
Meanwhile, you can open next-token probabilities and compare "Have a nice" with "It's Friday afternoon. Have a nice". Then click a token that isn't the most likely one and keep going: each token you pick becomes part of the text the model reads next. Play around with a few sentences to see what's going on.
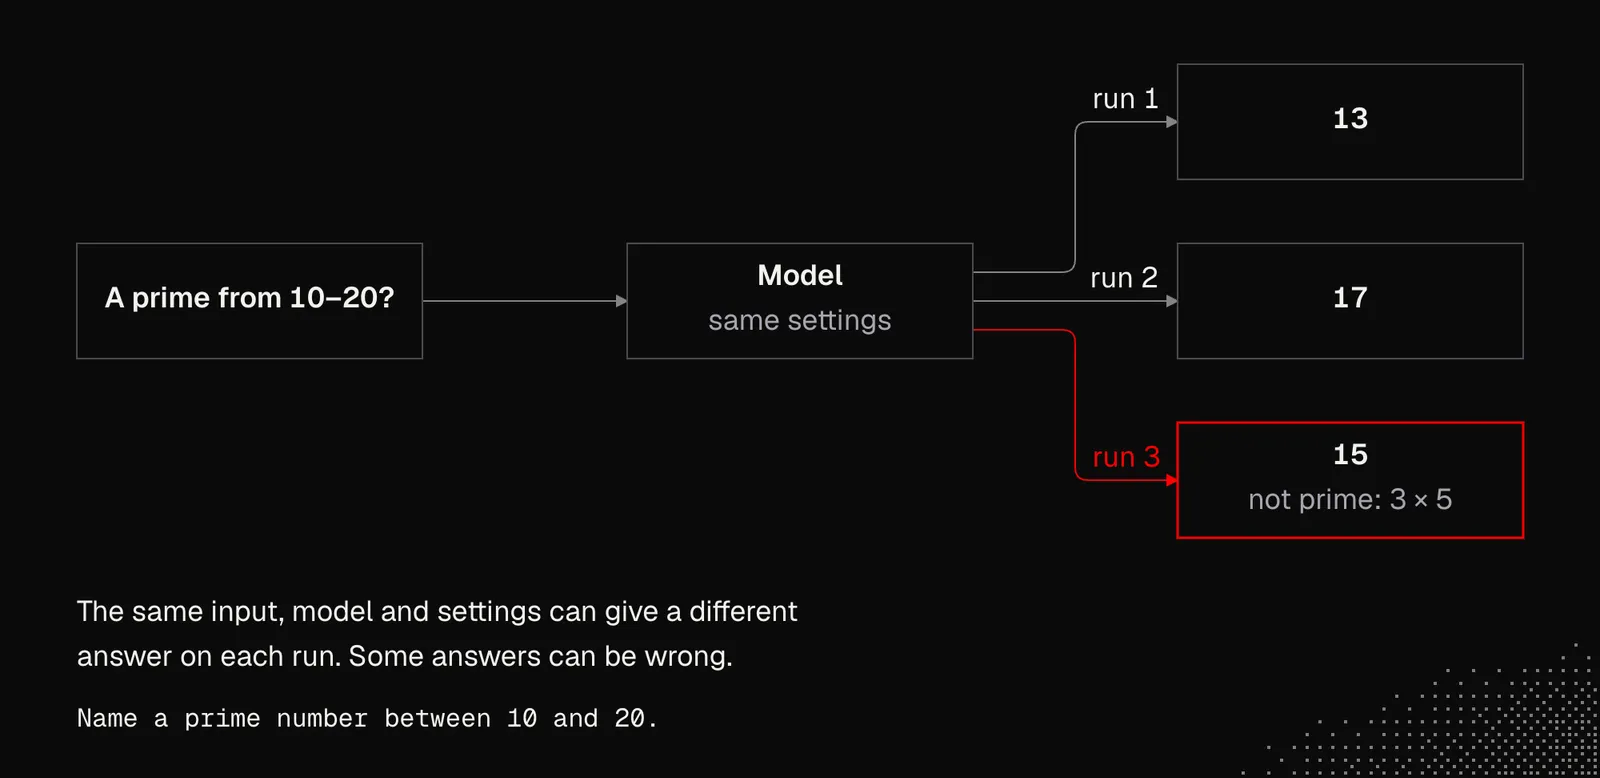
Non-determinism: Even with the same input, LLMs do not always produce the same output. This is not only due to the model and its settings; hardware can also play a role, as discussed in Defeating Nondeterminism in LLM Inference. For us, this means we can never be fully sure of the results produced by a language model, regardless of how the prompt and settings look. This is the exact opposite of what we've learned about programming over the years.
When we interact with LLMs through an API, we can control parameters such as temperature and top_p, which affect how the model chooses the next tokens. Setting temperature to 0 means the most probable tokens will be chosen, but this doesn't guarantee repeatable outputs.
Confabulation (or hallucinations): Generative models are trained on vast but limited datasets and produce results based on probabilities. Their knowledge does not cover everything and is limited in time - we call it knowledge cutoff. Their behavior also strongly depends on the available context and the task. As a result, models make mistakes, and working with them is not about certainty but about increasing the chance of getting the results we want. A very good read on this is Why language models hallucinate. It's worth knowing that we have no solution for eliminating confabulation entirely.
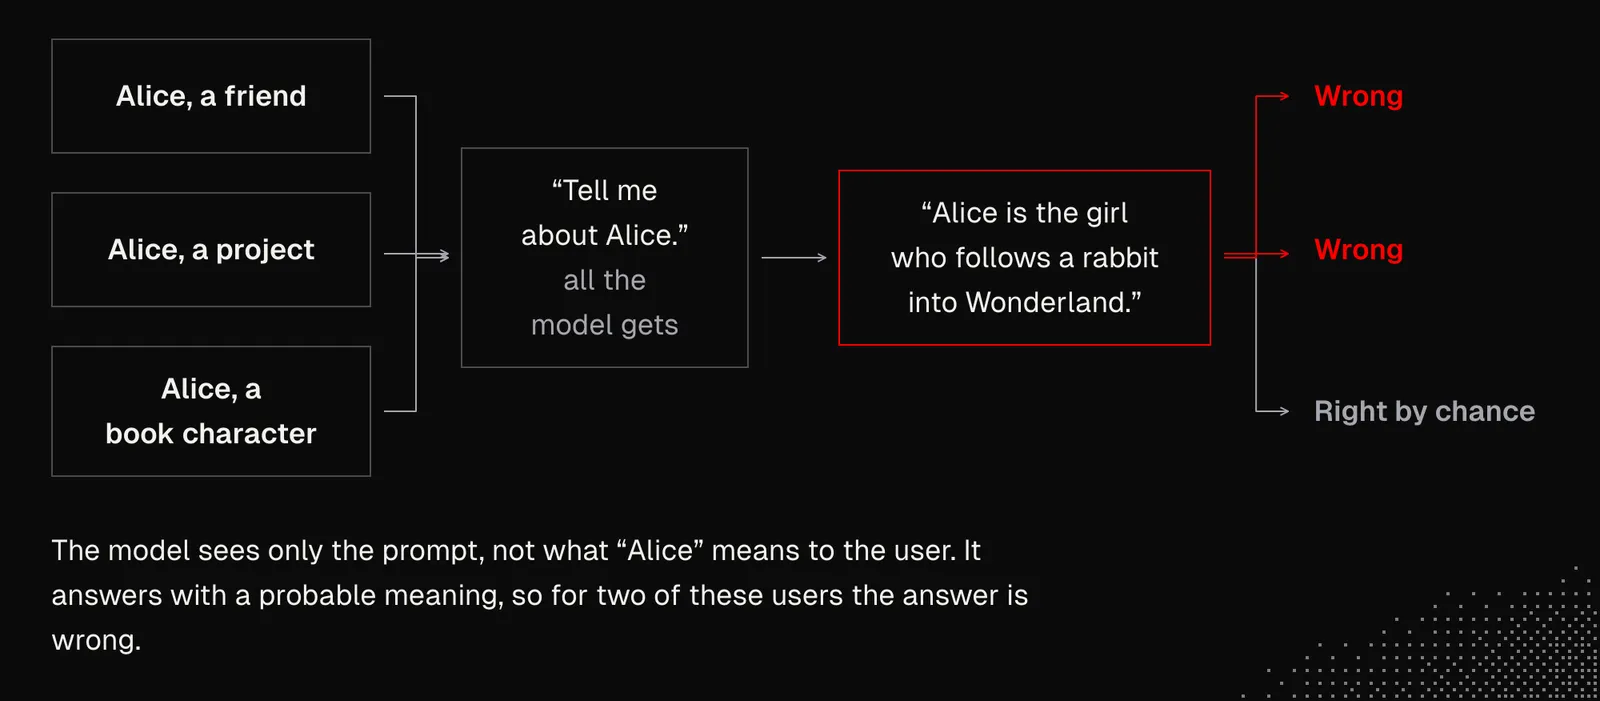
Run the Confabulation probe to ask "Tell me about Alice." with no context and then with two different contexts. The answer with no context can change, but strict hallucination is now rare and mostly comes from wrong or missing context.
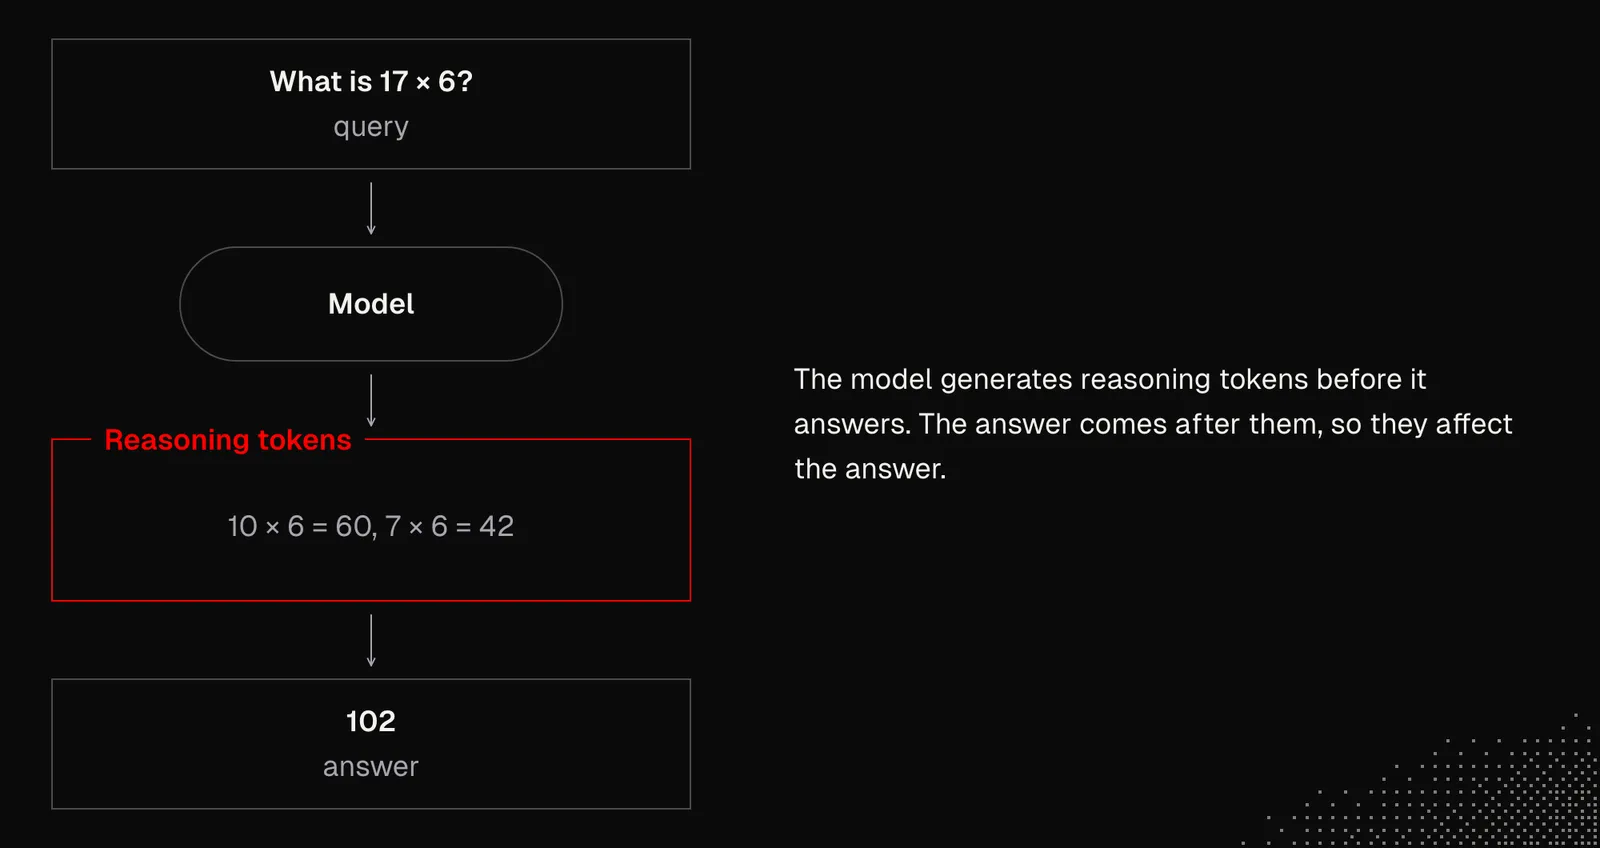
Reasoning: Language models "think" in two ways: visibly, by generating "thinking" tokens before the answer, and silently, within a single forward pass. Anthropic's "Verbalizable Representations Form a Global Workspace in Language Models" shows that the silent part goes through the J-space, a small set of word-like representations that plays a role similar to the global workspace in the human brain.
More thinking often leads to better results, but it also takes more time and costs more. Reasoning settings vary by provider, and we can often adjust them. However, the right setting depends on the model and the task we want it to handle.
This is clearly visible in Reasoning effort that sends one checkable task at each effort level and compares reasoning tokens, time and cost with whether the answer is correct. It's worth comparing with a smaller model to find the lowest level that still gets it right.
But there are signs that reasoning isn't quite what we might have expected: models, especially smaller ones, fail at a task simply because the information is presented in a different order (Premise Order Matters) as we can observe here.
We're not just talking about theory here, but about the foundations of generative AI as we've seen it over the past few years. Most of these mechanics have remained the same since ChatGPT's release in November 2022 and remain useful whether we work with agents, build harnesses or build agents from scratch.
Mechanics of Large Language Models
To take the way we work with agents to the next level, we need a clear understanding of their core mechanics so we can use their strengths and avoid their weaknesses.
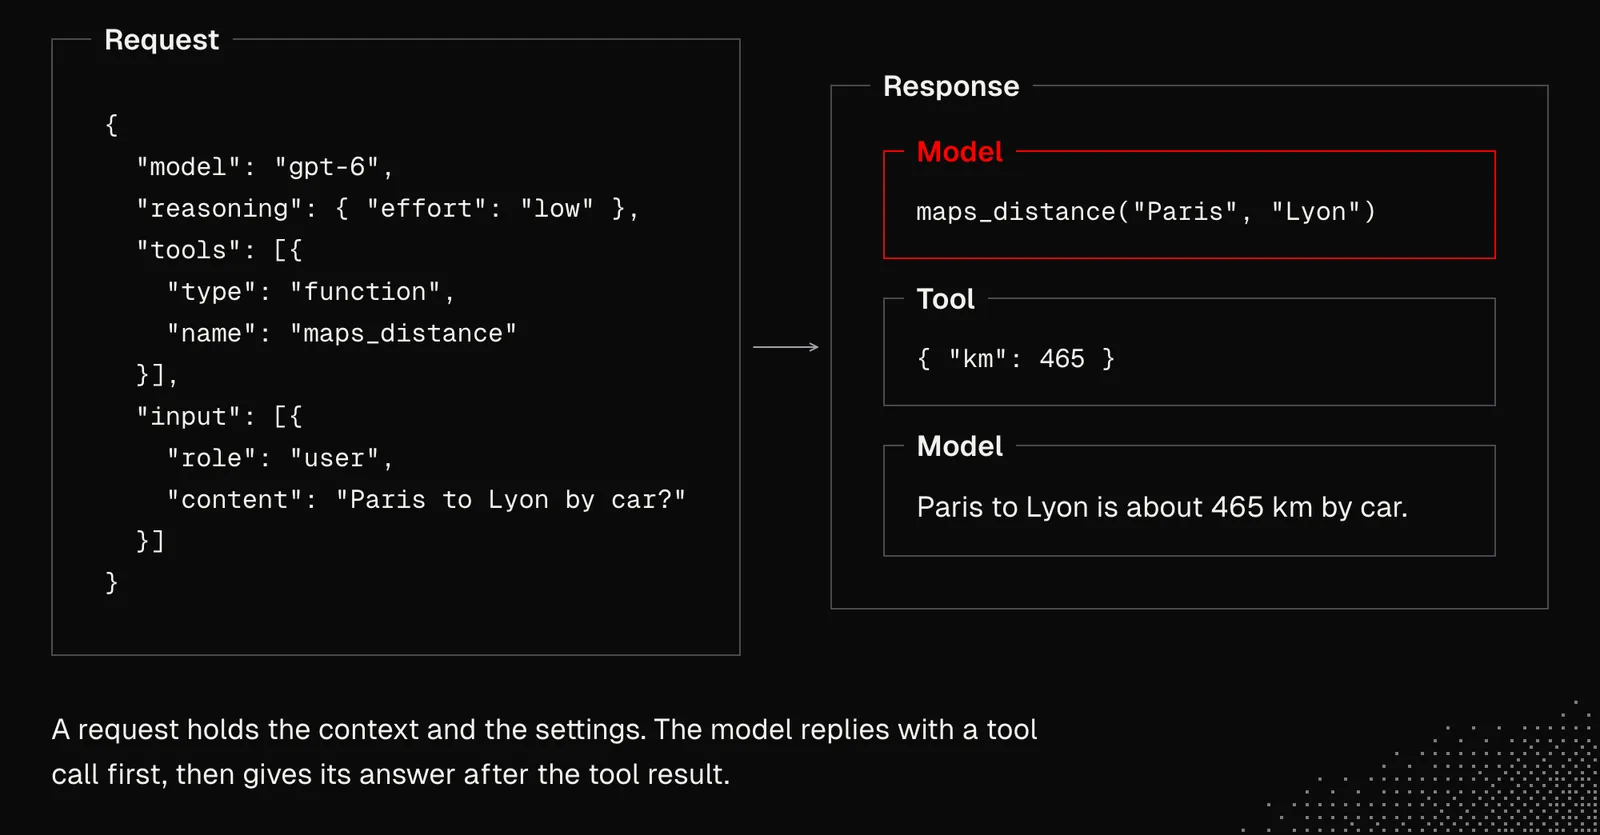
Request: Each request to an LLM includes context and settings. The context is often an array of messages that needs to be "completed" with an AI response. The settings include the model and reasoning level, as well as the available tools and platform-specific fields. Currently, the most popular format for interacting with an LLM API is the Responses API. You can try it in the Responses API request example and see the raw JSON sent to the provider and the JSON it sends back. Find usage, and notice that output is a list, not a single string.
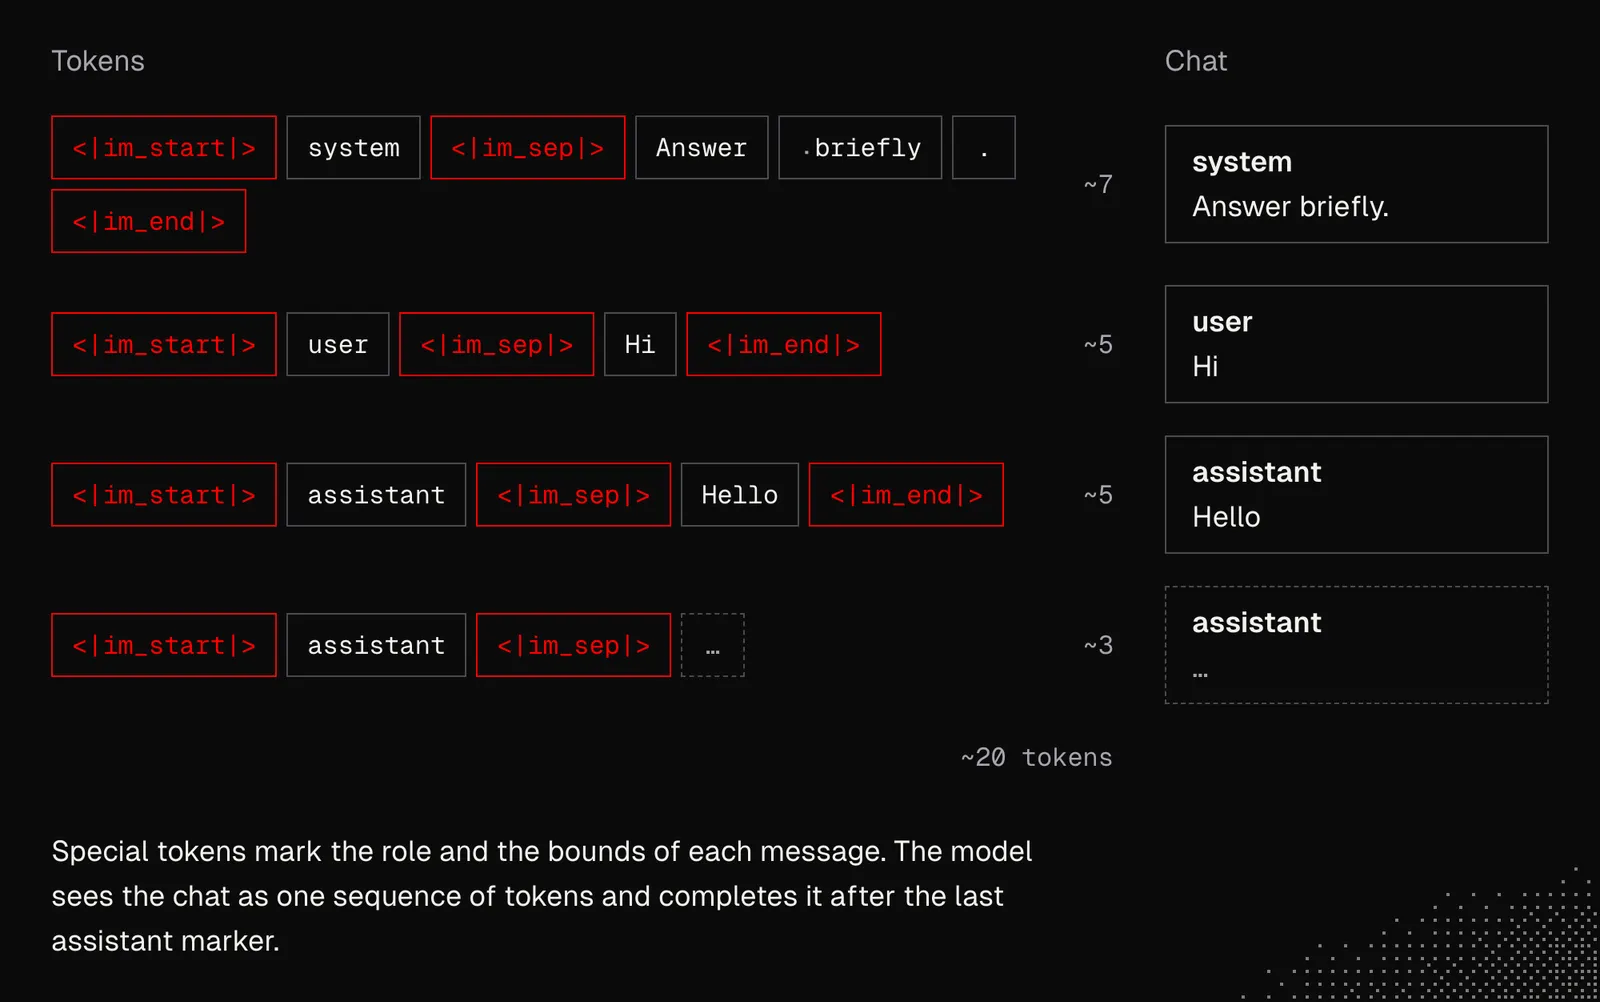
Completion: LLMs generate content by "predicting the next token", and the fact that we can chat with them is only due to a format called ChatML that structures the processed context using special tokens. You can play with it using Tiktokenizer. Modern LLMs structure their responses using special tokens, so we can easily tell what the user said, what was generated, and which instructions were provided by the developers of the tool we’re using. In other words, from the model's perspective, chat messages are just text.
Open Chat template to see the thread from the figure below as text the model reads, with special tokens around each role. Then type <|im_end|> into a user message: it becomes six ordinary tokens, so a user cannot close their own turn.
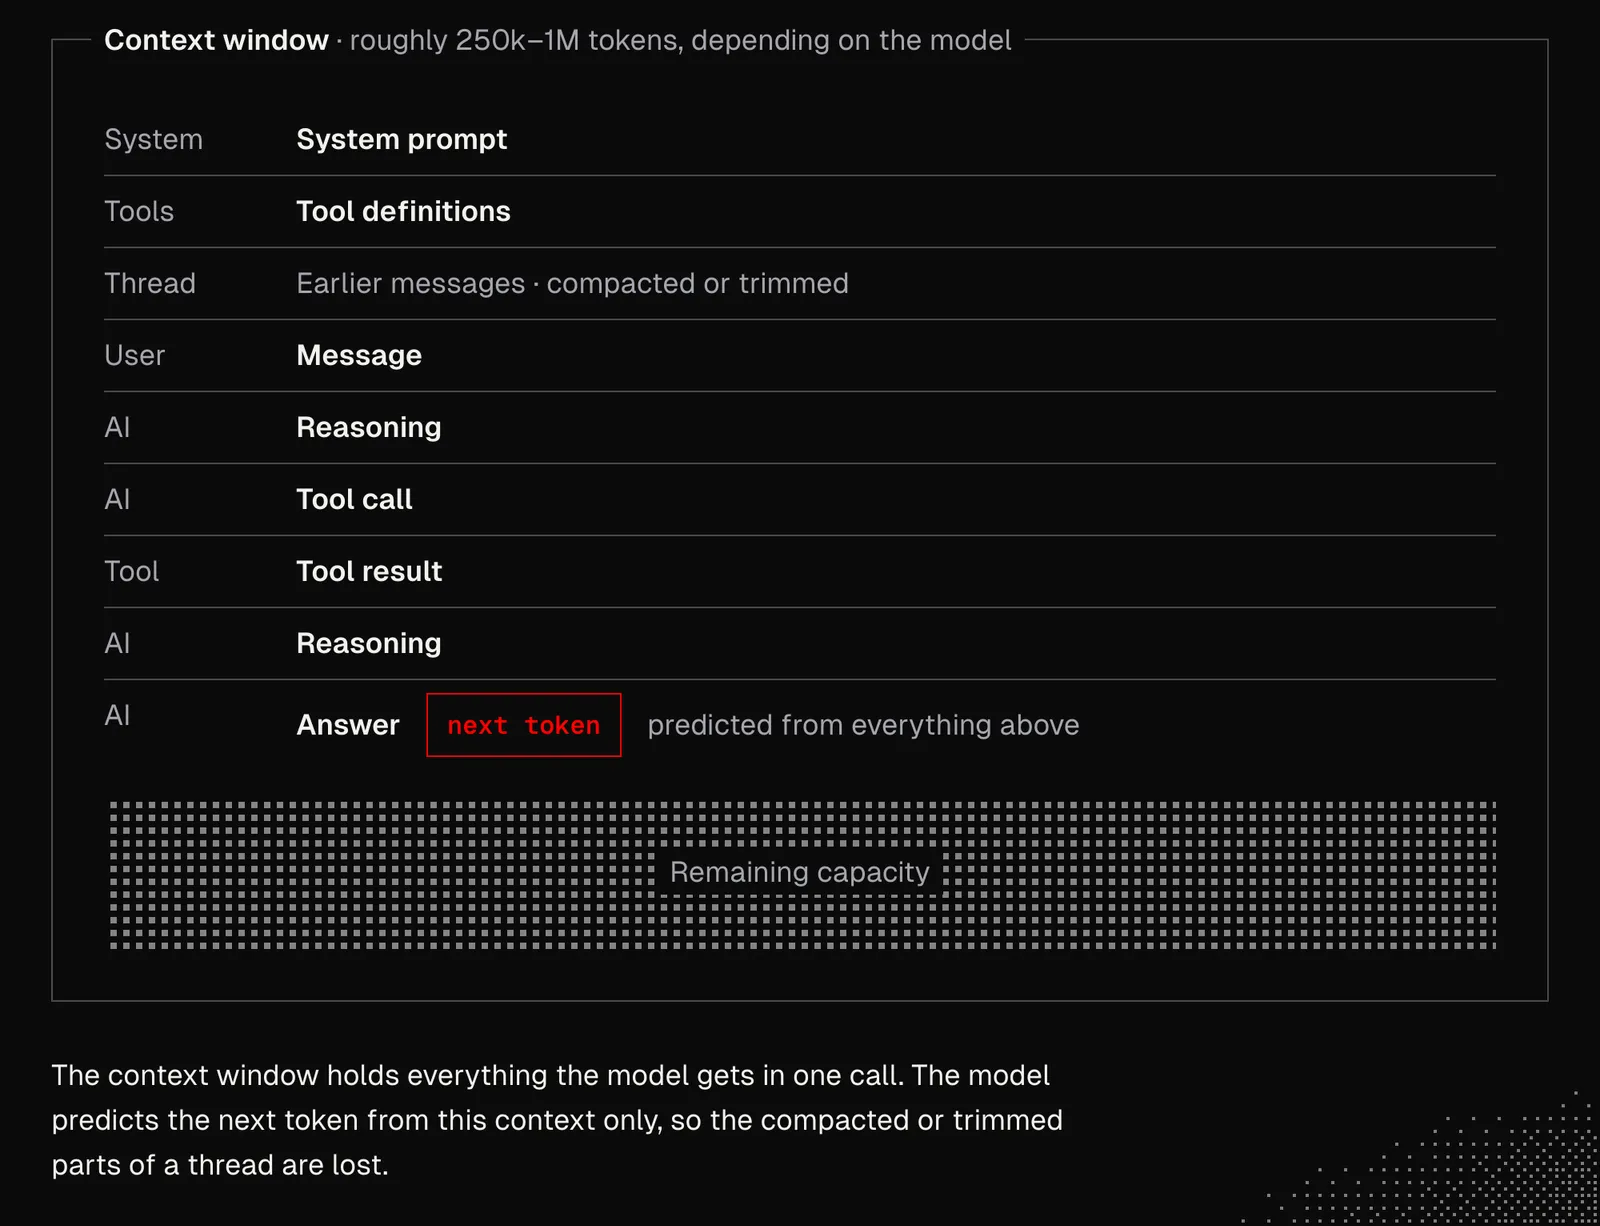
Context Window: LLMs need all the content required to generate a response, but the amount they can handle is limited to roughly 250k–1M tokens, depending on the model. In practice, we rarely hit this limit because tools use various forms of auto-compaction.
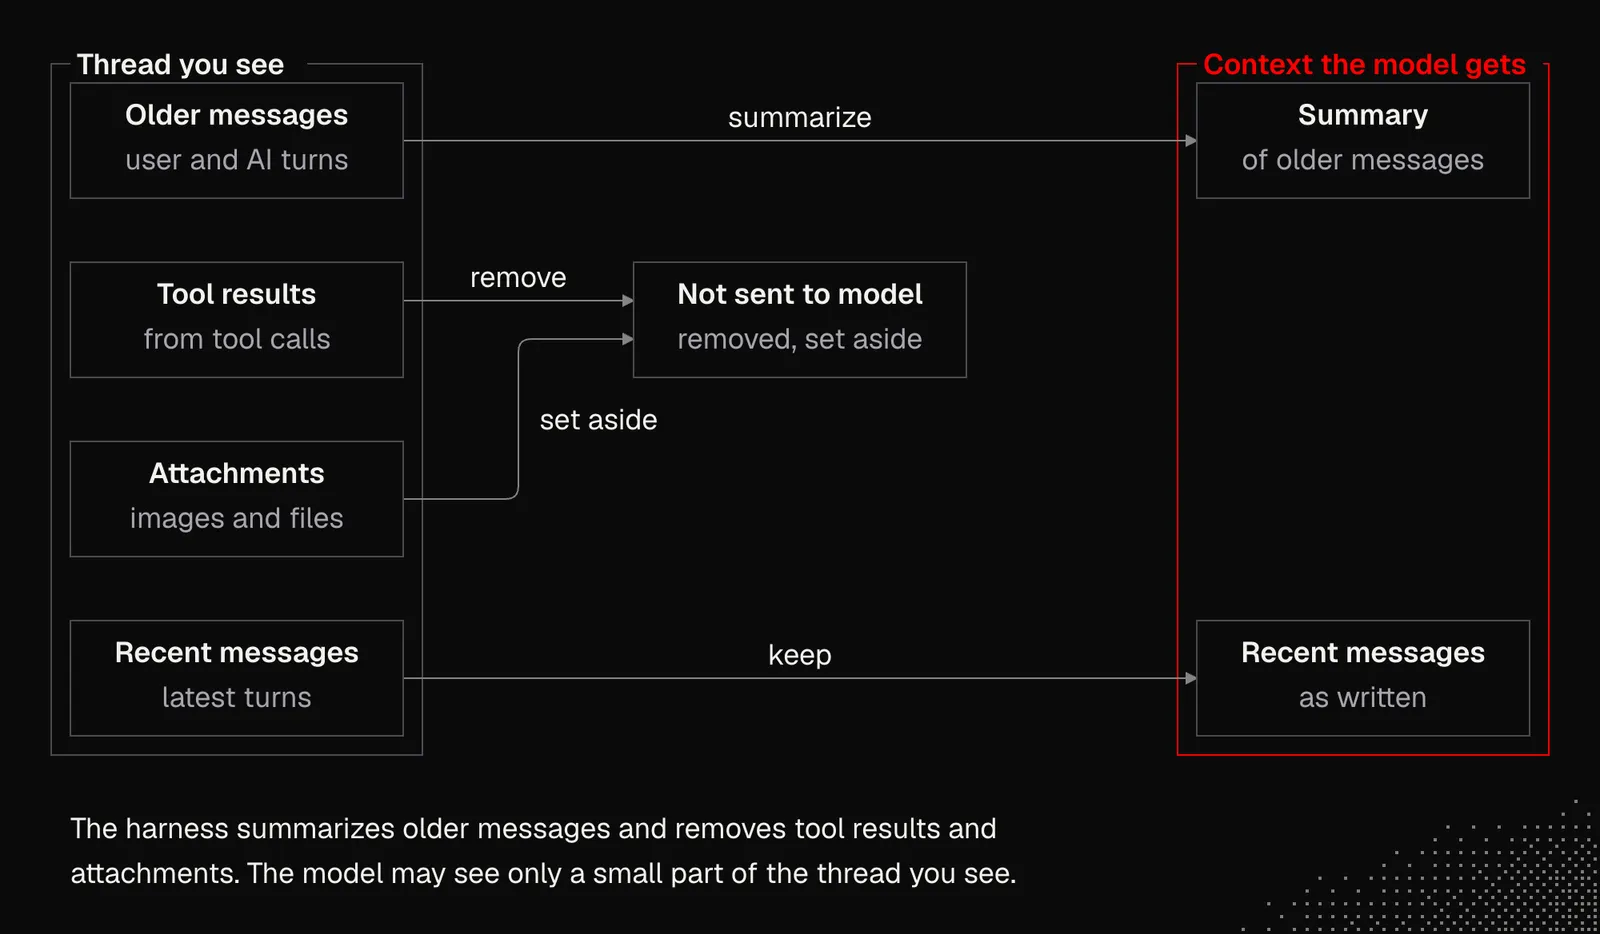
Still, it’s worth remembering that not everything in a thread is passed to the model. At the same time, we know that the model predicts the next token based on the context available so far. This makes longer conversations with agents lossy, as some information gets compressed or trimmed.
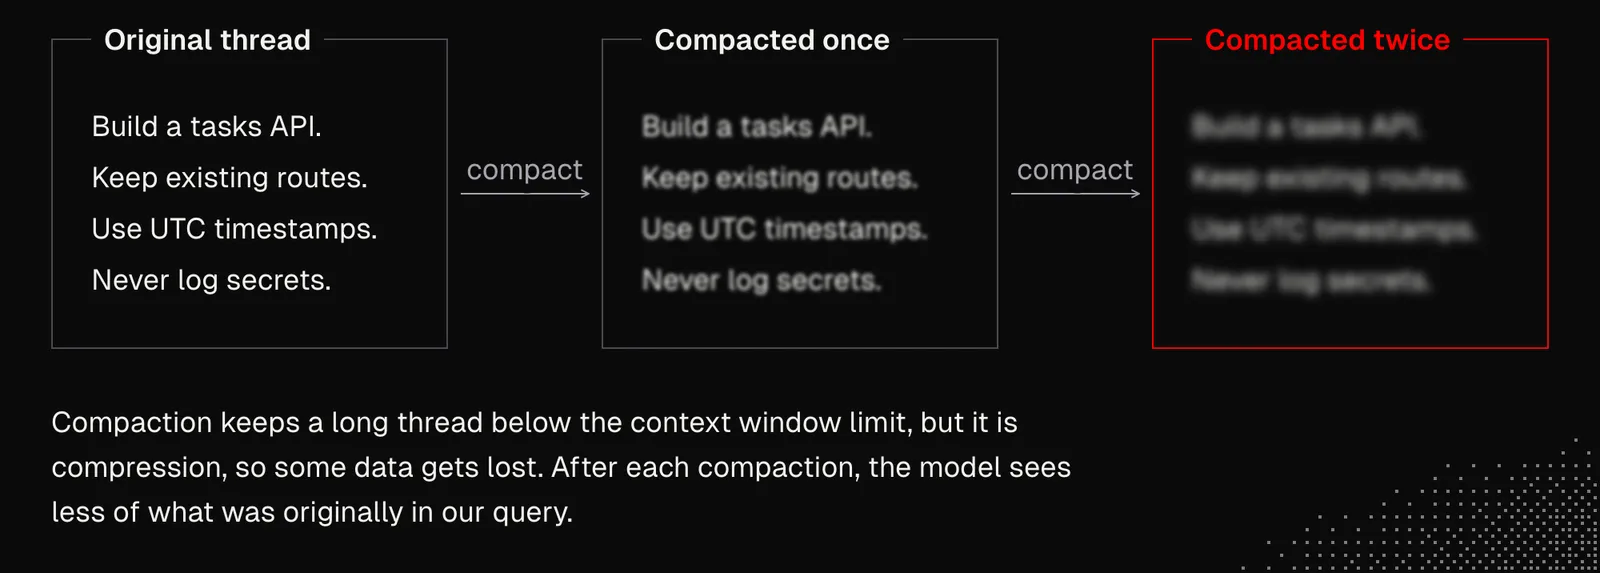
While context compaction keeps getting better over time, we're still talking about compression, so some data gets lost or gets extracted. Either way, the model loses sight of what was originally in our query, making it less likely that we'll get the result we asked for.
Context compaction strategies differ from harness to harness, but in Context compaction we can see how compacting a coding thread three times loses some information, which silently leads to degraded performance. Then run it with --words 50 and compare which facts get lost.
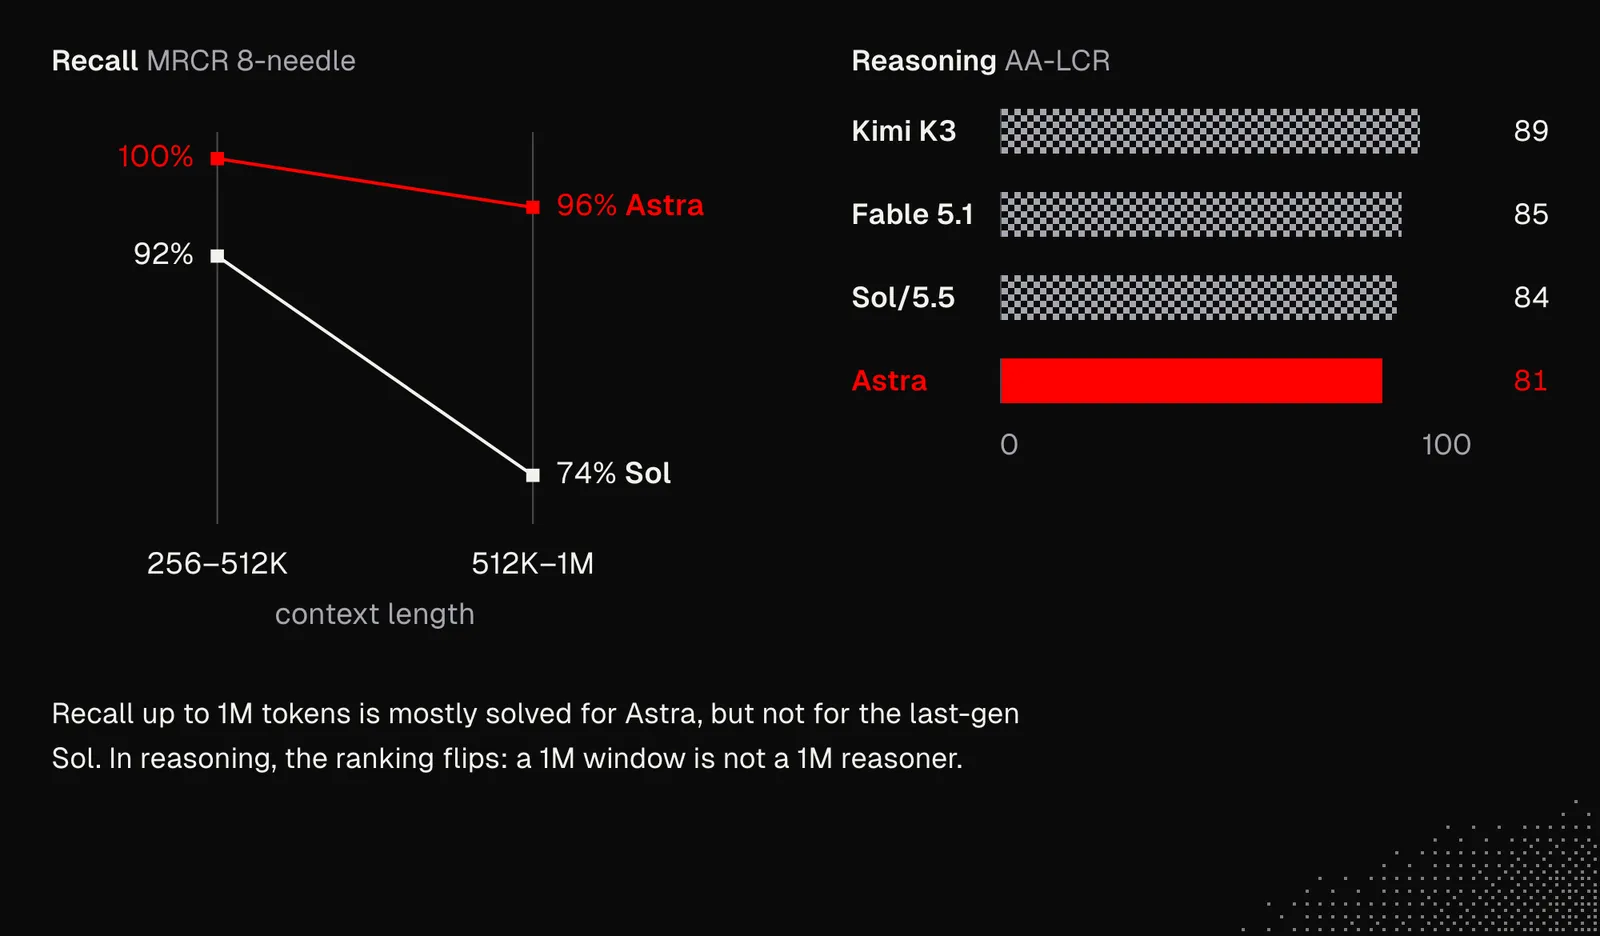
Context Understanding: The fact that an LLM can handle 1M tokens does not mean using that many is a good idea. A model’s reasoning performance still drops with longer contexts, and as a rule of thumb, models perform best when using less than 30–40% of their context limit. For simpler tasks, such as retrieving information from a long text, the latest models perform really well.
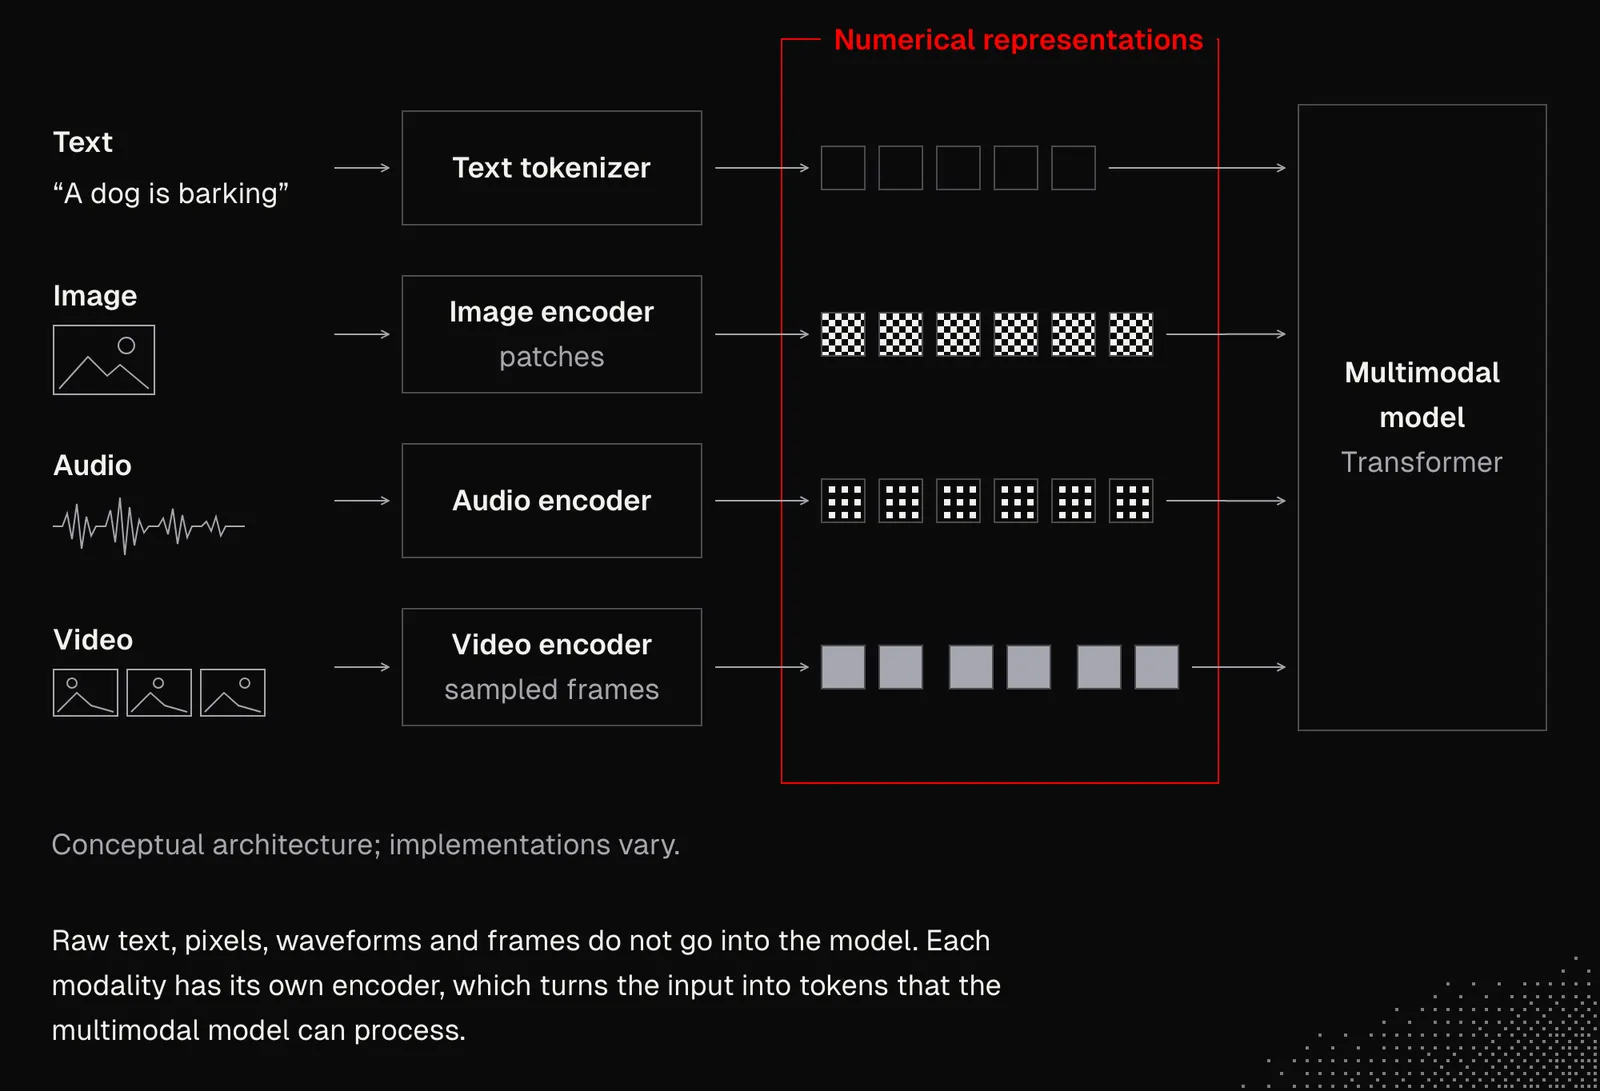
Multimodality: Models have different capabilities, and some of them can process not only text but also images, audio and sometimes even video. To make this possible, data has to be tokenized as well (but in a different way) and then processed by a model. The important part is that models process numbers, not actual information, so they perceive images, audio and even text differently from how we might initially expect. For example, language models often struggle to understand details such as overlapping elements, exact colors, or even the time on a clock.
Structured Outputs: A model can generate text and structure it as a JSON string that can be easily processed in code. This way, we can extract information from unstructured documents, and this also allows us to use language models in application logic that often takes the form of agents.
To see how this works, run Structured output for Kyoto and for Tarvenmoor, a city that does not exist. Both answers pass the schema check: a schema controls the shape of the answer, not its truth.
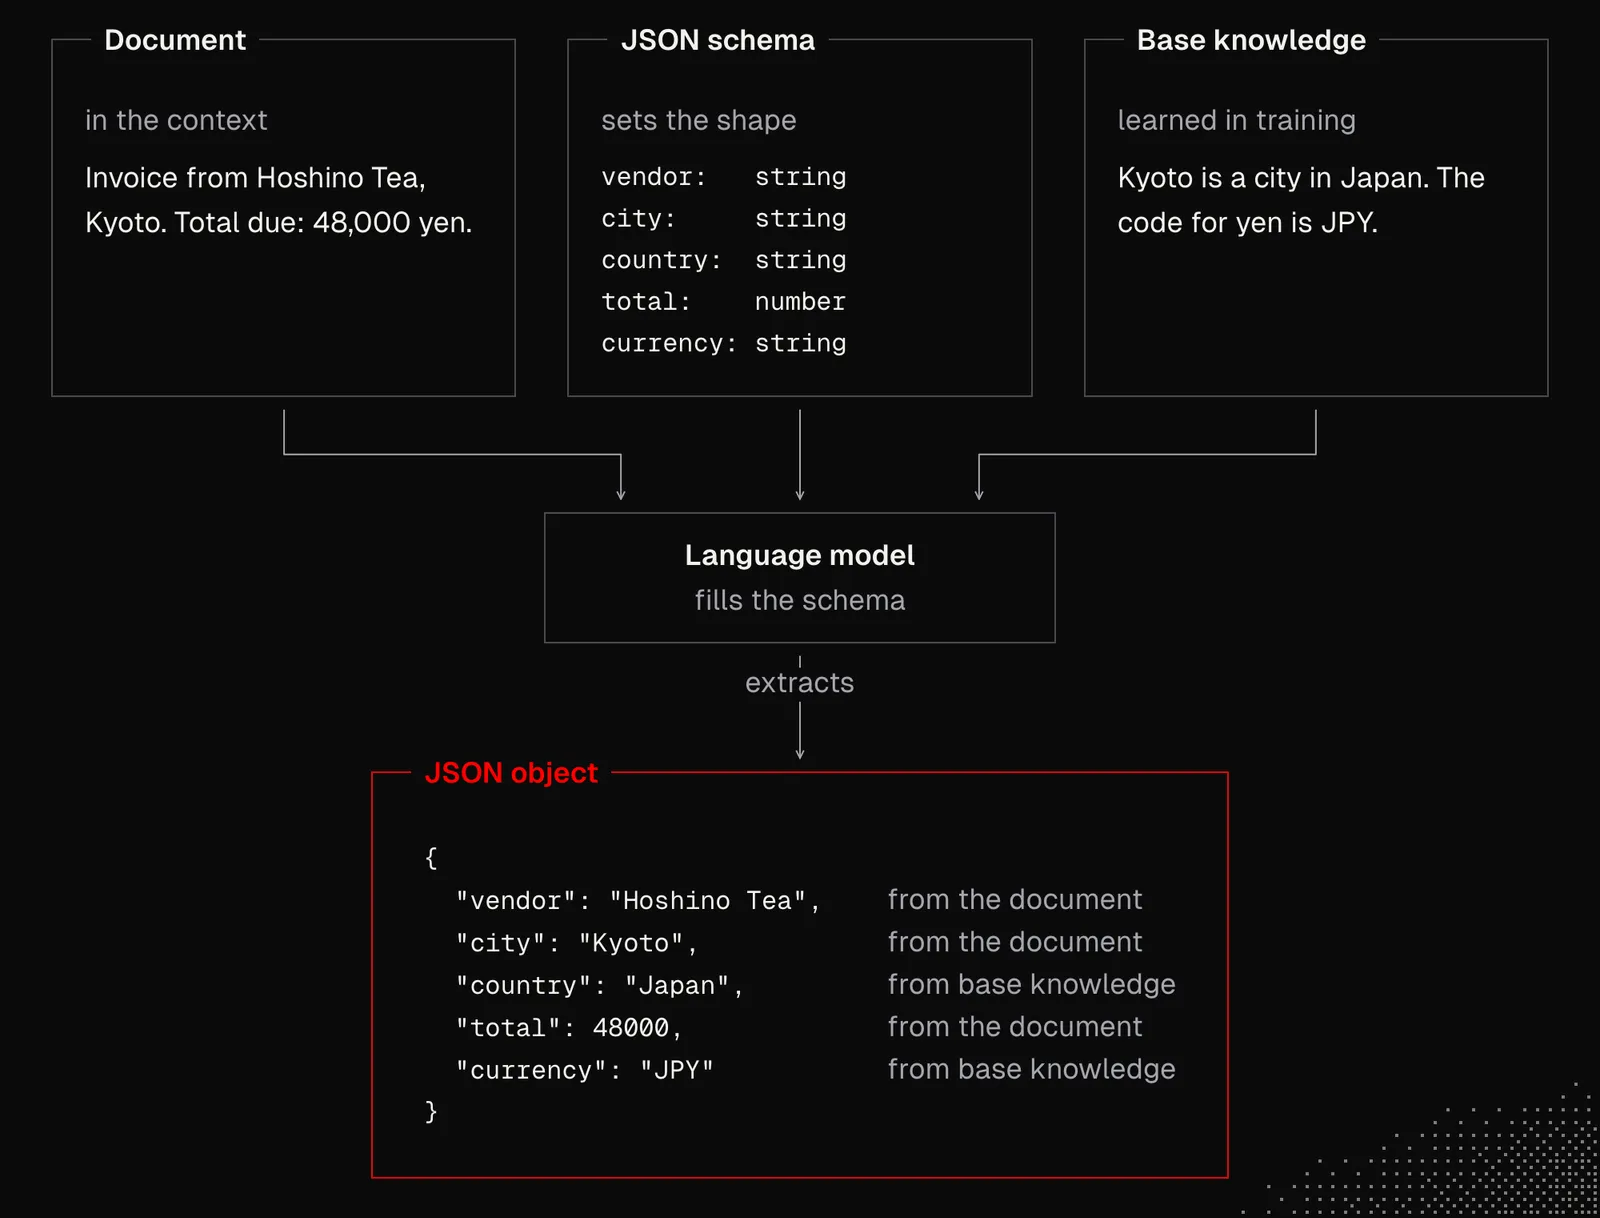
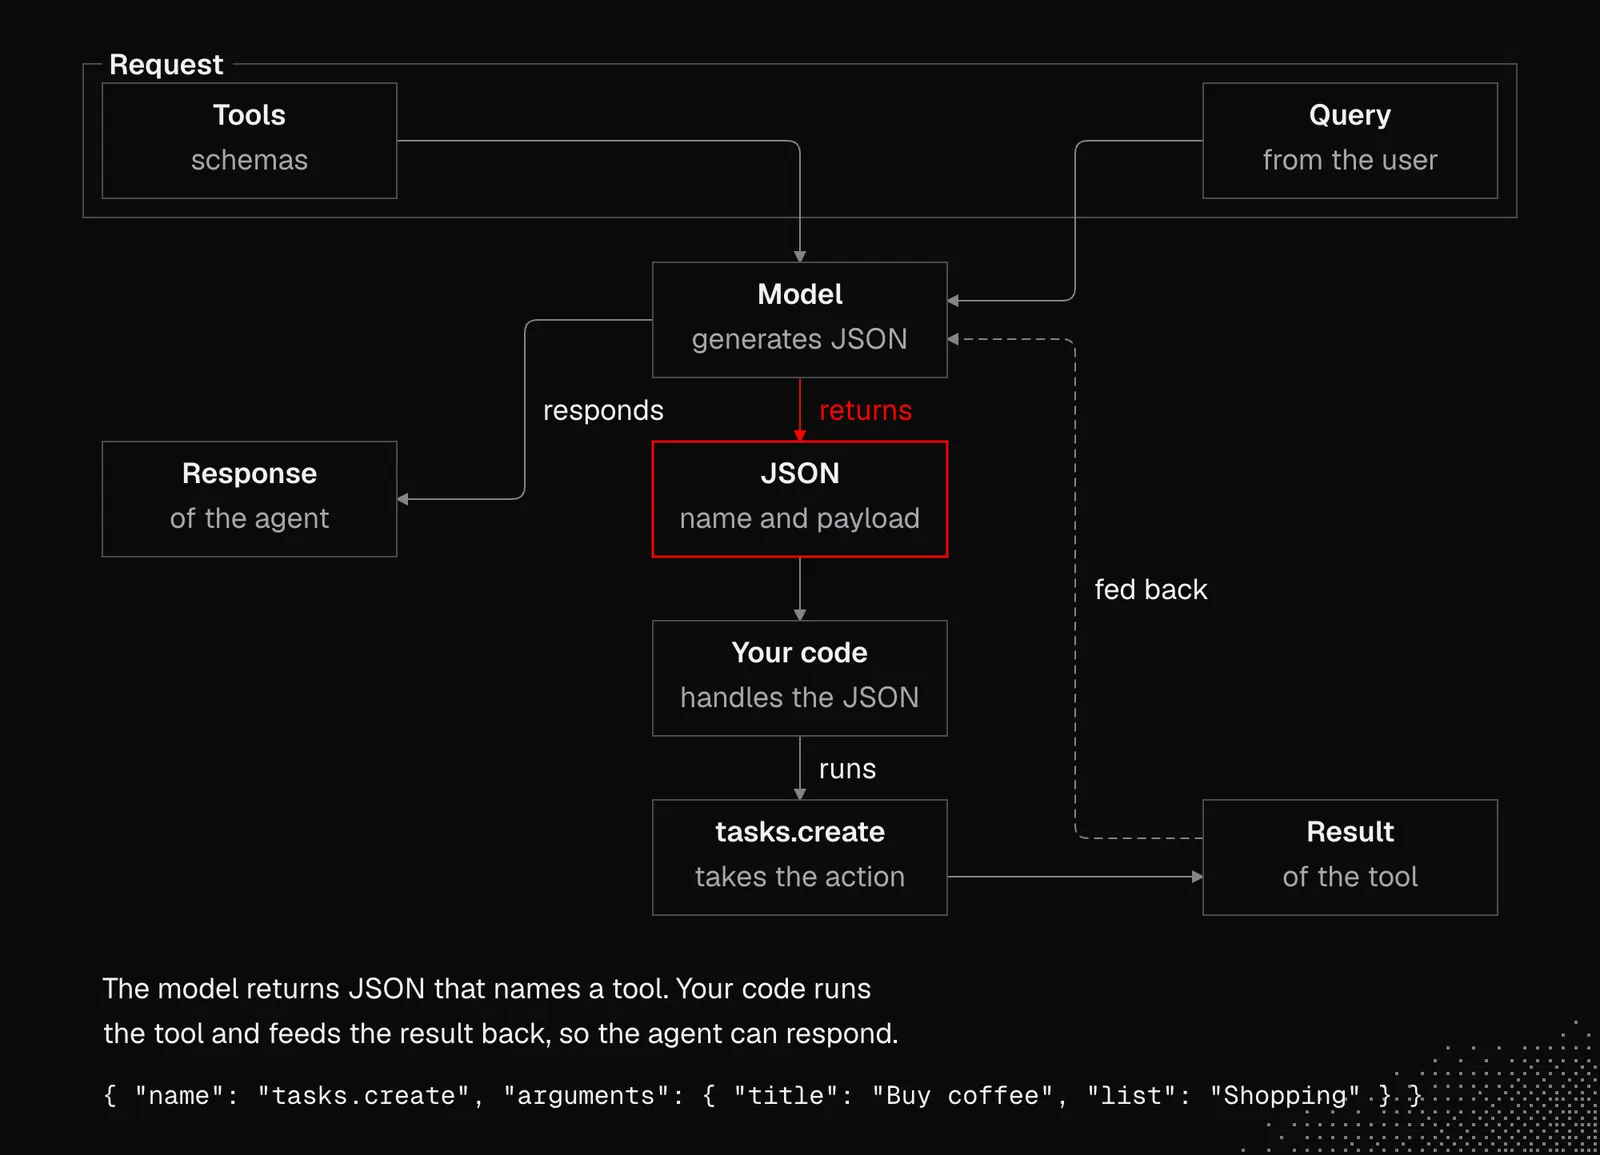
Function Calling: Since models can generate JSON strings, one of the returned fields may be a function name, so they literally point to a tool that needs to be used. This information is handled in code to perform the action with the generated payload and feed the results back to a model.
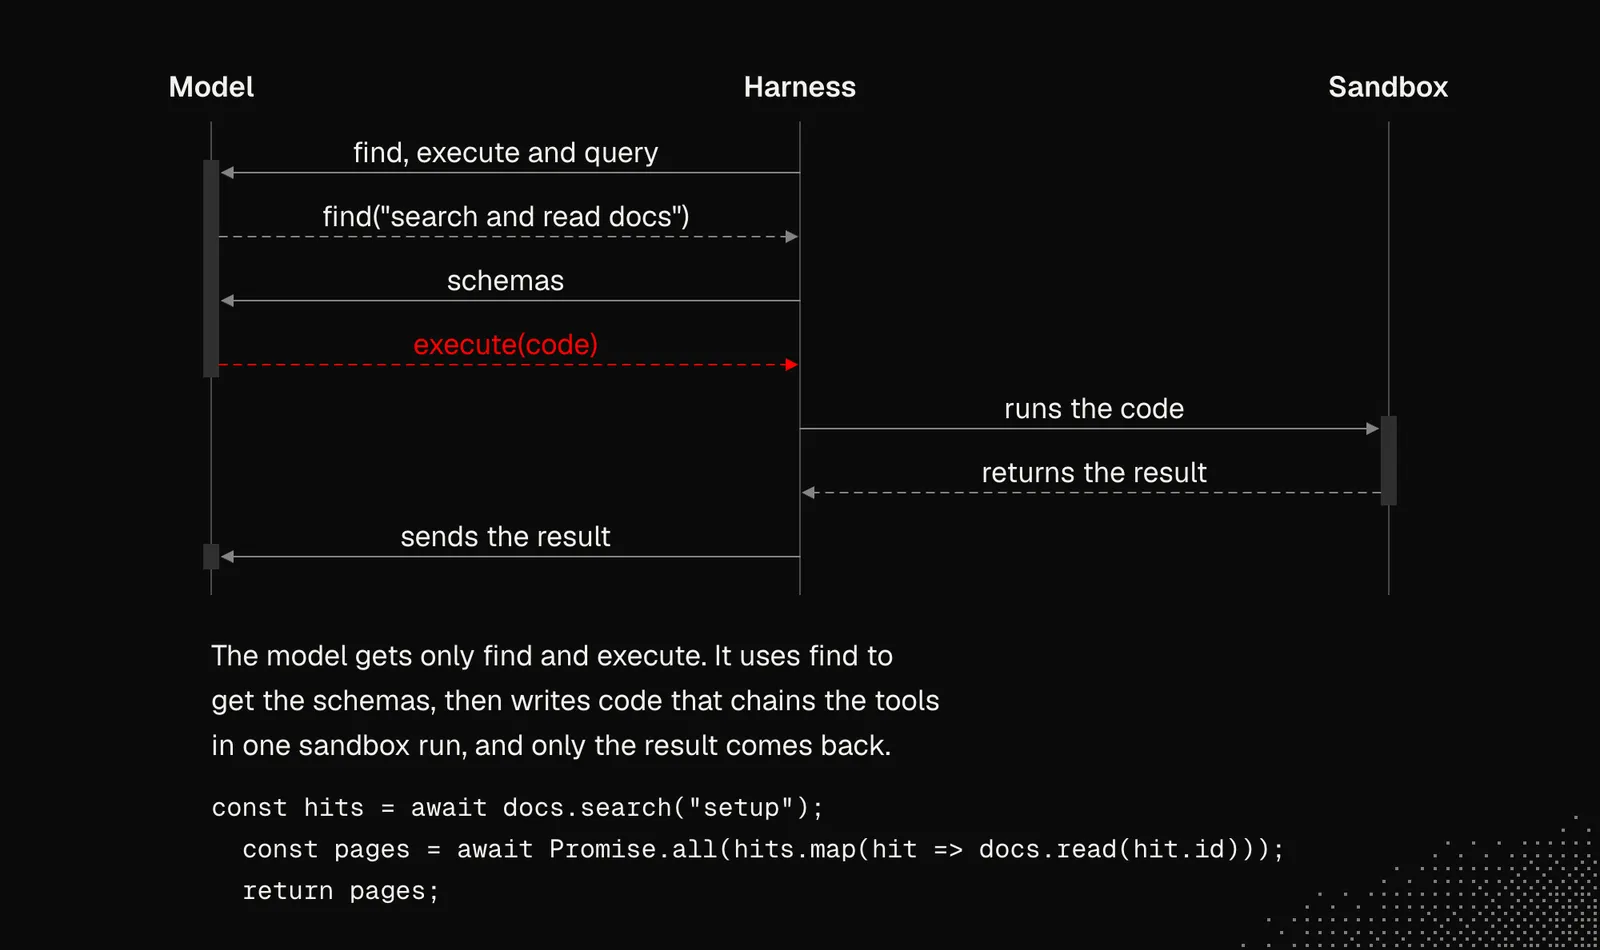
Code Mode: Function Calling requires all schemas to be present in the context, so the model can decide which tool to use. But we know the context window has its limits, and it's a waste to include all this information even if the interaction does not need it. At the same time, the latest models have become very good at writing code.
This leads us to a scenario in which a model can be provided with only two tools, such as "find" and "execute". This is enough for the agents to write code using available capabilities. It's more efficient than function calling in almost every aspect, but it's more difficult to deploy to production, since code has to be executed in sandboxes such as Daytona or Cloudflare. For coding agents that live on our computers, it's often much easier because they run scripts locally.
The difference shows in Code mode, where we run the same task twice: once with 30 function tools and once with only find and execute. In our runs of the default task, function calling spent about 2,300 of its 3,000 input tokens on tool schemas. Try asking "Who am I?" too: a one-call task can cost more in code mode.
LLMs can’t physically interact with their environment, and there are strict limits on how much information they can process. But they can return structured data that we can use to make API calls. This lets us quickly move our interactions with AI "from answers to actions", and we’re already seeing this in agent tools such as Claude Code, Devin, Hermes, and Grok Bot.
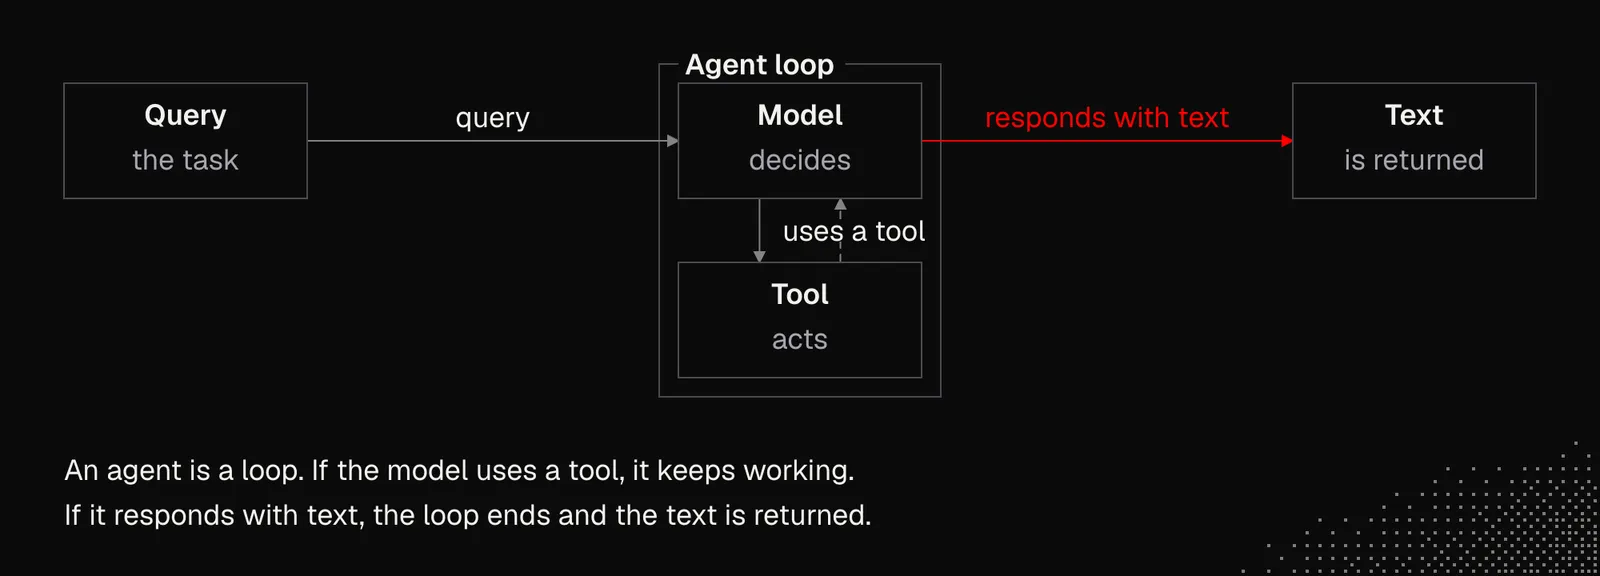
Agents: Some definitions say that agents are just loops of LLM calls. While a minimal agent can be implemented this way, building agents becomes much more complicated when they need to be durable and able to perform long-horizon tasks. This will be covered in detail in the second week, so for now, let's just remember that an agent is a loop in which the model decides either to use a tool and keep working on the task, or to respond with text, which ends the loop and gets returned.
Agent loop shows a basic agentic loop step by step: a tool call keeps the loop going, and text ends it. Set the step limit to 1 to see the loop stop before the model can answer.
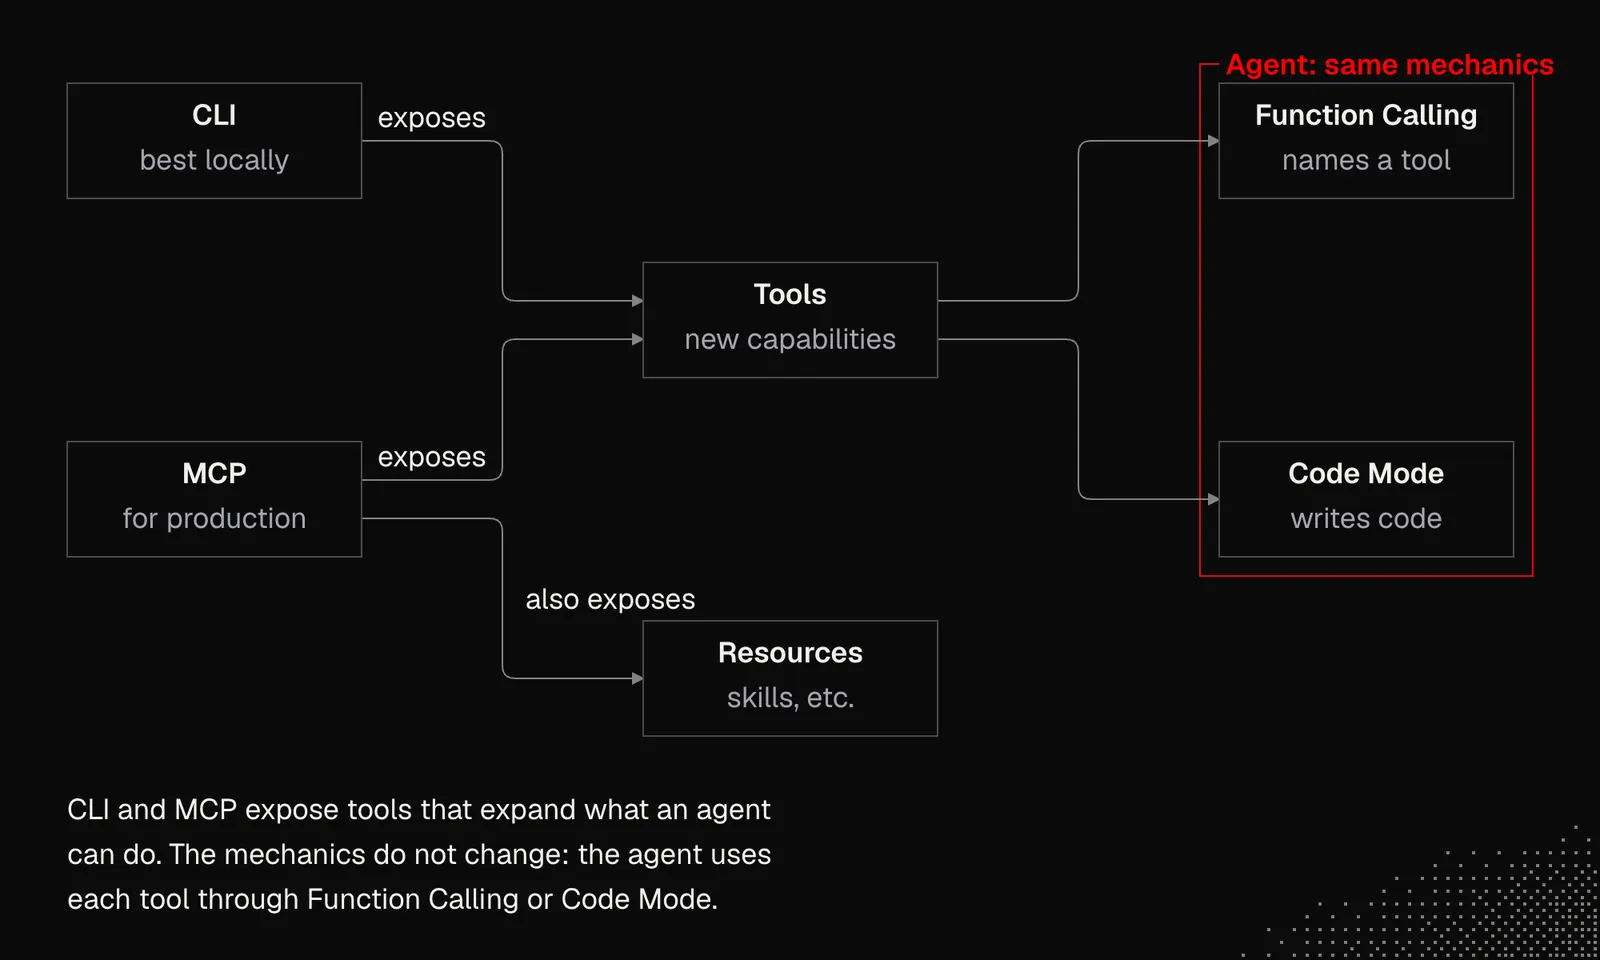
CLI / MCP: agents may receive native tools exposed by the harness, but they can also use well-known CLI tools, which work best locally. For production, MCP (Model Context Protocol) is a much better option. It's widely used and supported by nearly all tools, such as Claude, ChatGPT, Grok Bot and others. For now, it's enough to know that CLI / MCP can easily expand an agent's capabilities by exposing tools that it uses through either Function Calling or Code Mode. A good example is the very popular Playwright MCP, which lets the agent interact with a browser.
Platforms and Harnesses
Most of us will work with AI tools such as Cursor, Claude Code, Pi, or T3 Code. While each offers some unique features, they all share the same foundation: a language model. The real difference lies in the "package": roughly speaking, how they use the model's native strengths and address its weaknesses, and how that ultimately affects UX and overall efficiency.
To make working with AI simple, harnesses often hide the underlying mechanics, so we don't need to worry about them. The problem is, doing so requires generalization so the solution works for most users.
For example:
- Auto Compaction addresses context window limits, so we can have long threads without errors. Under the hood, there's often more compression and trimming going on, and this leads us to believe that "our agents know what we are talking about", while in practice they may see only a small part of what we do.
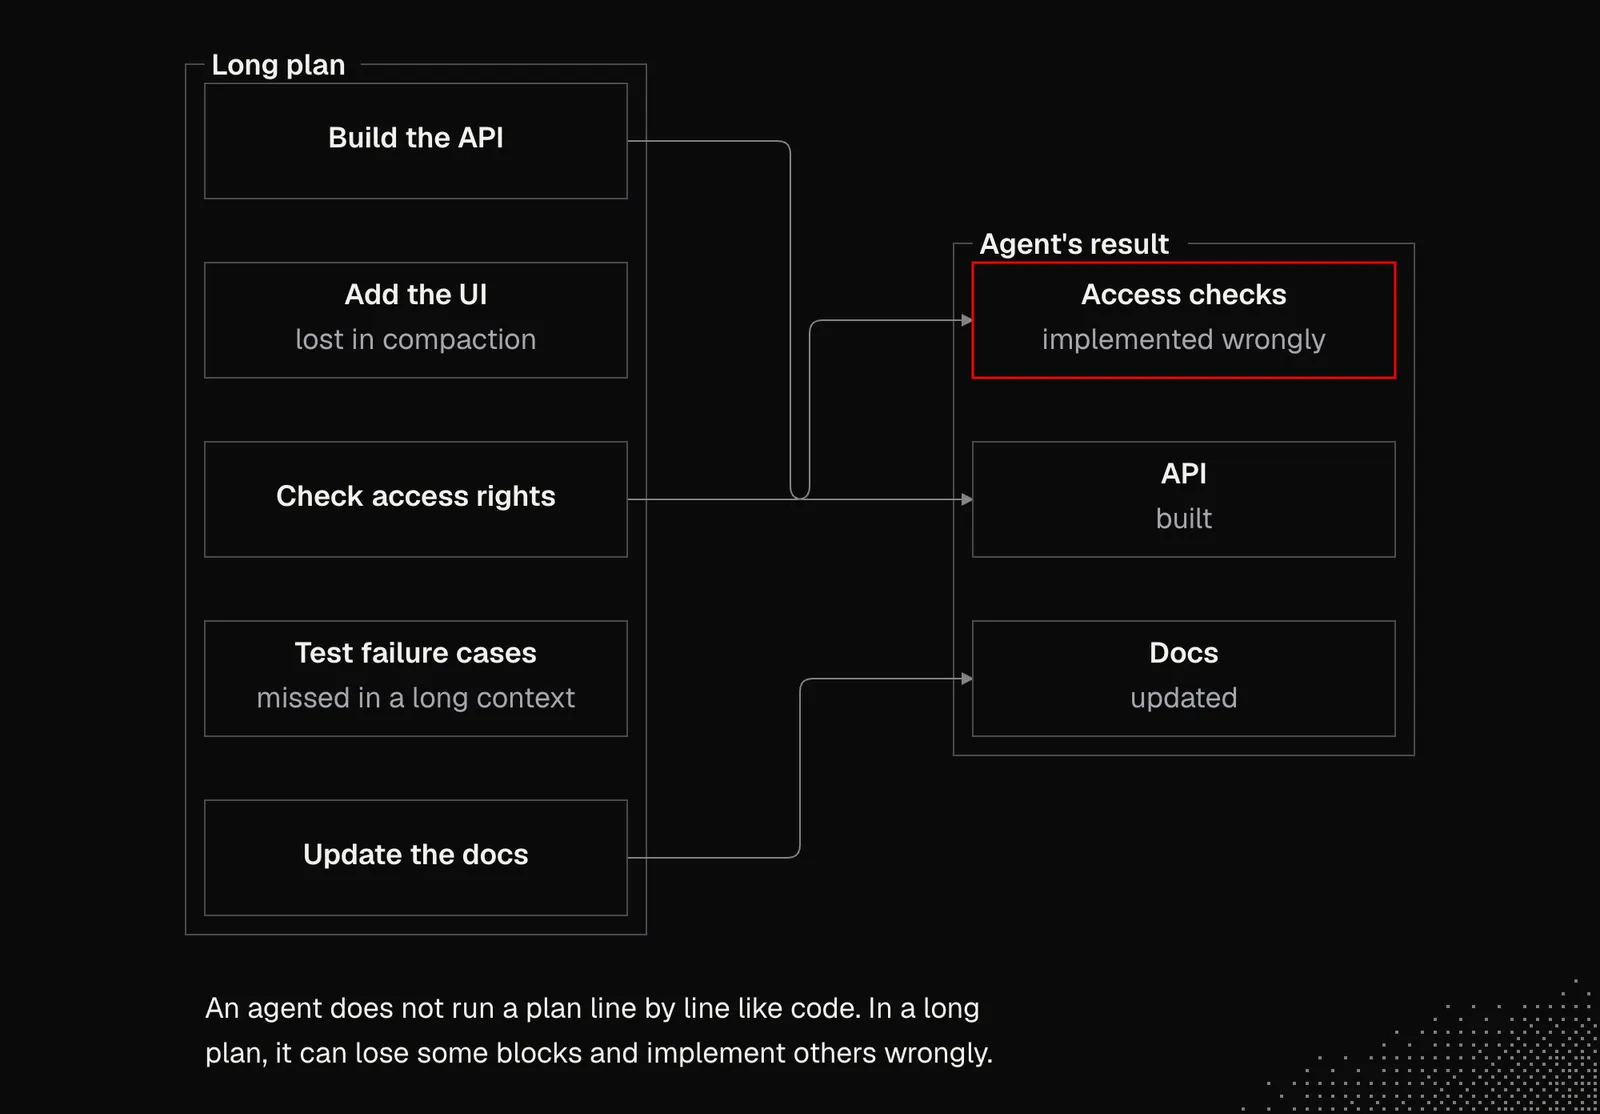
- Plan Mode: Agents often encourage us to plan our work in a dedicated mode focused on adding context and clearly describing the task. This helps unless the plan becomes too broad or too detailed. In either case, models struggle to follow all the rules in a single thread. A better idea is to split the plan into smaller tasks, but coordinating those tasks takes more time unless the agents can manage their own work, instead of using plan mode. We'll discuss this in the upcoming lessons.
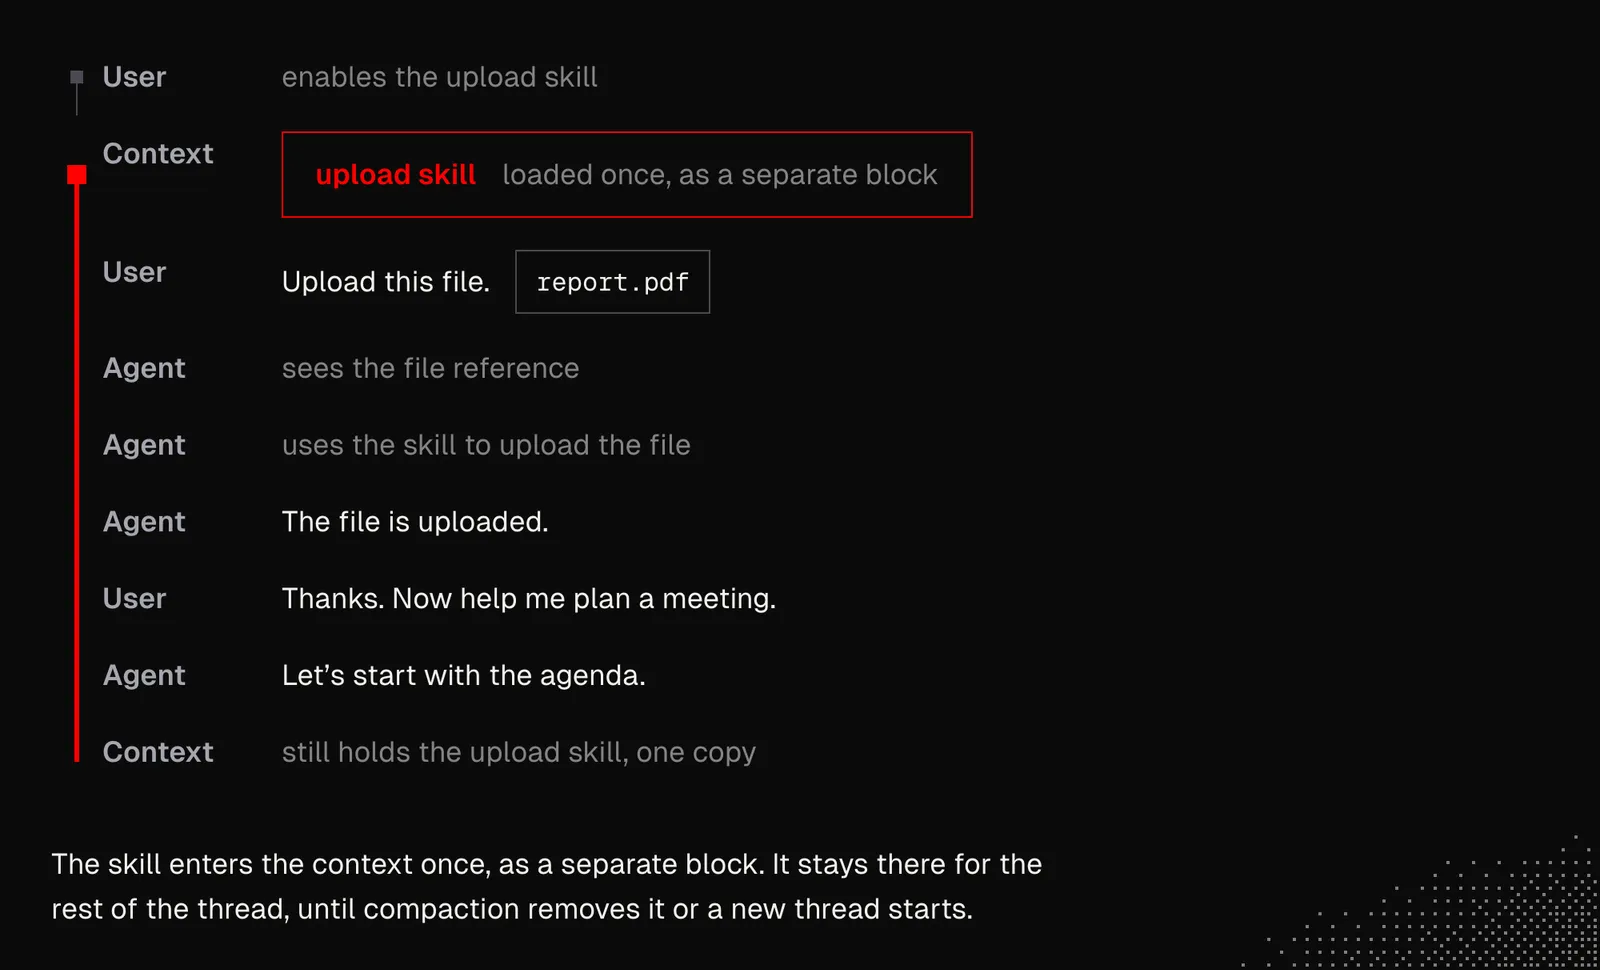
Skills are files (or folders) with instructions and sometimes scripts, designed to steer a model towards certain behaviors. The thing is, once enabled, they often remain in the context until compaction removes them or we start a new thread. The model can also trigger a skill on its own, but it chooses based only on the skill's name and description, since skills can't all be injected into the context at once.
Skill selection shows six skills, added to the context as names and descriptions only, loaded across 15 test requests. Most of the requests succeed, but in some of them a skill isn't picked when it should be, or is selected when it's not needed.
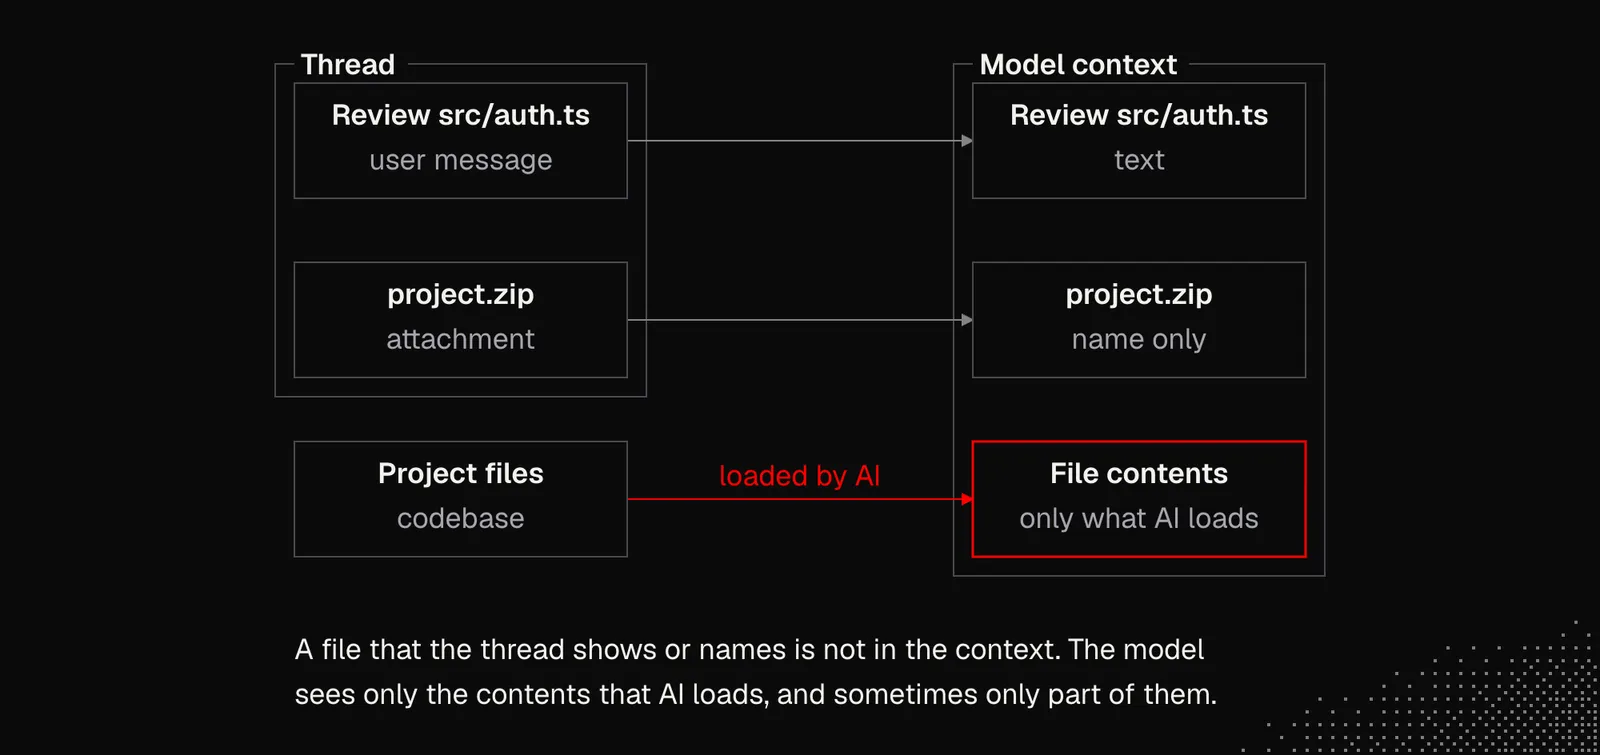
- Attachments like images or any other files, or even references to them, are often presented as if they are entirely visible to a model. But they almost never are. Their content has to be loaded by AI, and sometimes it gets loaded only partially. In other words, even if the UI suggests that some files and folders are visible to the agent, it does not mean they really are. The same applies to the entire codebase or any kind of knowledge base.
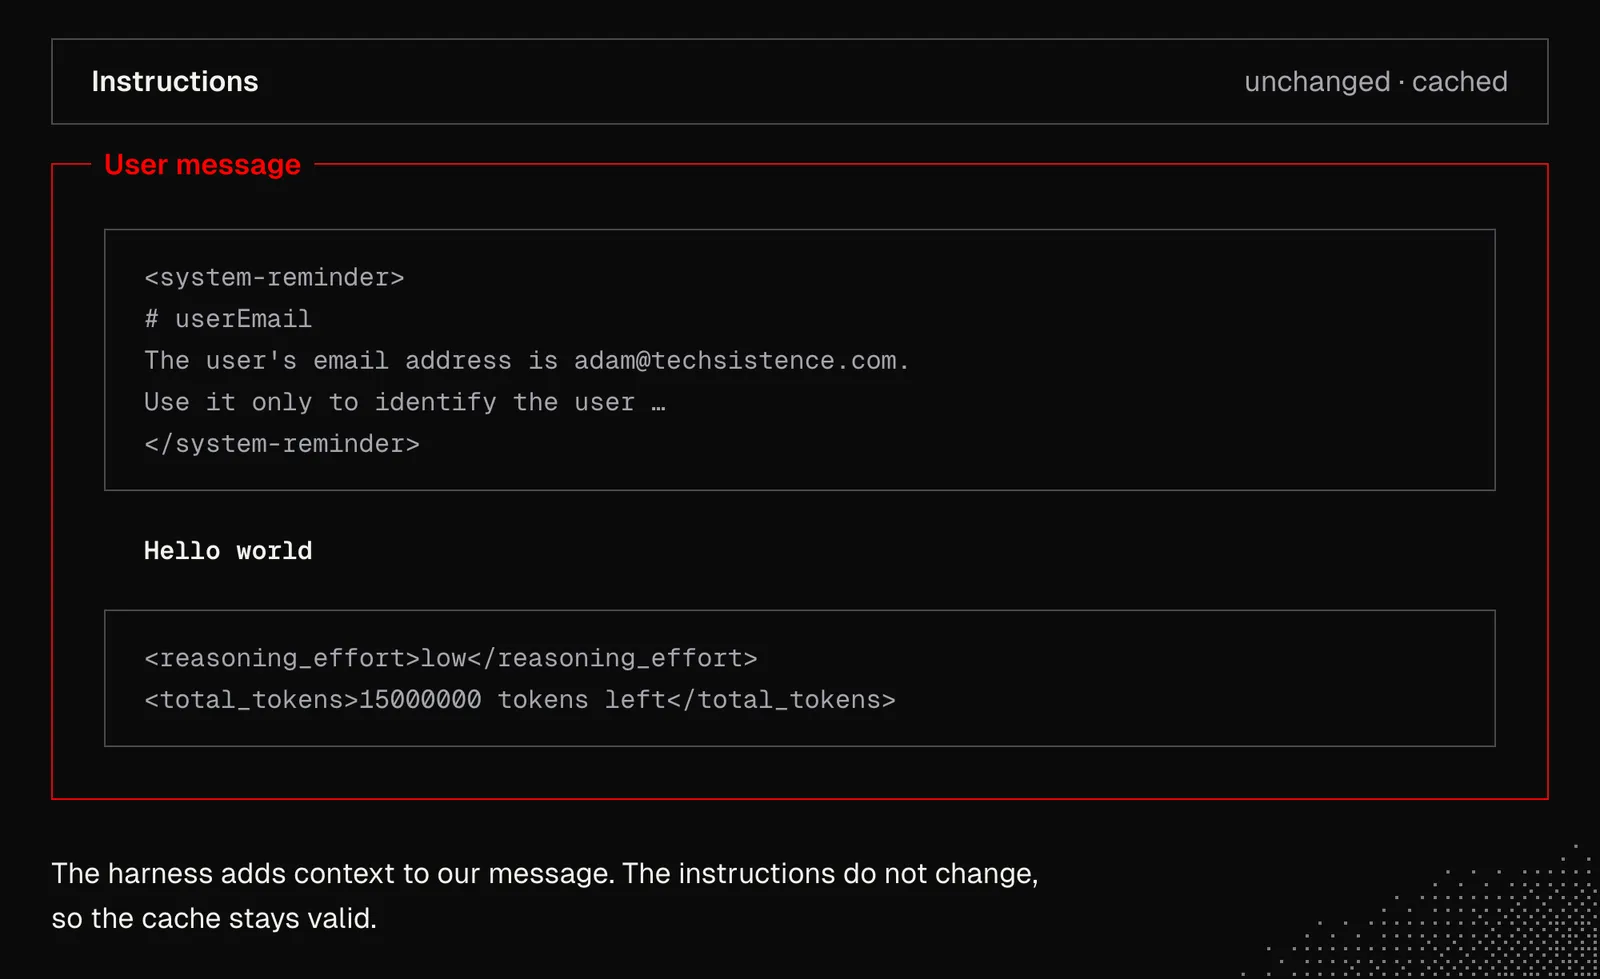
Environment: Some information can be sent to a model upfront, such as a general profile or some rules. But as we work with agents, the environment changes. For example, files get modified or a Git repository gets updated. The model has to be aware of these changes, but we can't modify its instructions because of the caching mechanism, which we'll discuss later. For now, all we need to know is that our message is not the only thing the model gets.
Put the Request inspector between your harness and the API, then send "Hello". Compare your message with the system prompt, the tool definitions and the
<system-reminder>blocks that the harness added. This example has a demo button that loads a sample from Claude Code.
Those examples show us some of the underlying mechanics of the tools we work with every day. Their behavior depends on how LLMs work in general and on the API provider, but it always affects our experience and the results we get from AI. Throughout the course, we'll explore even more behaviors like these and techniques for using them to our advantage.
Now, let’s take a closer look at popular providers such as OpenAI, Anthropic, xAI, and DeepMind / Google, their offerings, and their tooling.
- OpenAI offers GPT models and an almost complete range of multimodal capabilities, including image generation and editing, audio understanding and generation, and video generation. ChatGPT is its main product, and OpenAI shaped a popular API format called the Responses API.
- Anthropic offers Claude models and focuses on text generation and image understanding. Its main products are Claude and Claude Code.
- xAI aims to deliver a full range of multimodal capabilities. Its main products are Grok and Grok Bot.
- DeepMind / Google offers a full range of multimodal capabilities, including video understanding. It also has its own API format called the Interactions API.
- Bonus: we also have platforms such as OpenRouter, which offer easy access to models from all the major labs and a vast library of open-source models.
Technically, it's possible to tell which model is best at a given moment (see Artificial Analysis), but that changes frequently, so it's a good idea to avoid "vendor lock-in", especially since we may want to use a different model for a given task to optimize cost and speed, or multiple models for the same task to improve quality.
When working with AI, we'll almost always want to use the best models available, although there are some tasks we want to automate or run at scale. Then we may want to check if we can lower the reasoning settings or switch to a smaller model.
To avoid vendor lock-in, we'll discuss a harness-agnostic setup with tools that aren't tightly tied to a particular provider. For the top labs, being harness-agnostic and provider-agnostic is almost the same thing, because each of them has its own harness, such as Codex for OpenAI or Claude Code for Anthropic. For example, instead of using Codex, we'll suggest working with Pi, OpenCode, or tools like T3 Code or Superset.
Generalized Steering
You may have heard of prompting techniques such as chain of thought, few-shot prompting, or tree of thoughts, which were popular before the rise of LRMs (Large Reasoning Models). Then came general instruction files such as AGENTS.md, containing broad rules and personalization details.
Recently, there’s been a common belief not only that we don’t need additional control over the model, but also that it can do more harm than good. While there’s some truth to that, the reality isn’t so simple. We may still want to steer a model, not by giving it precise instructions to follow, but by guiding it toward certain behaviors. For example:
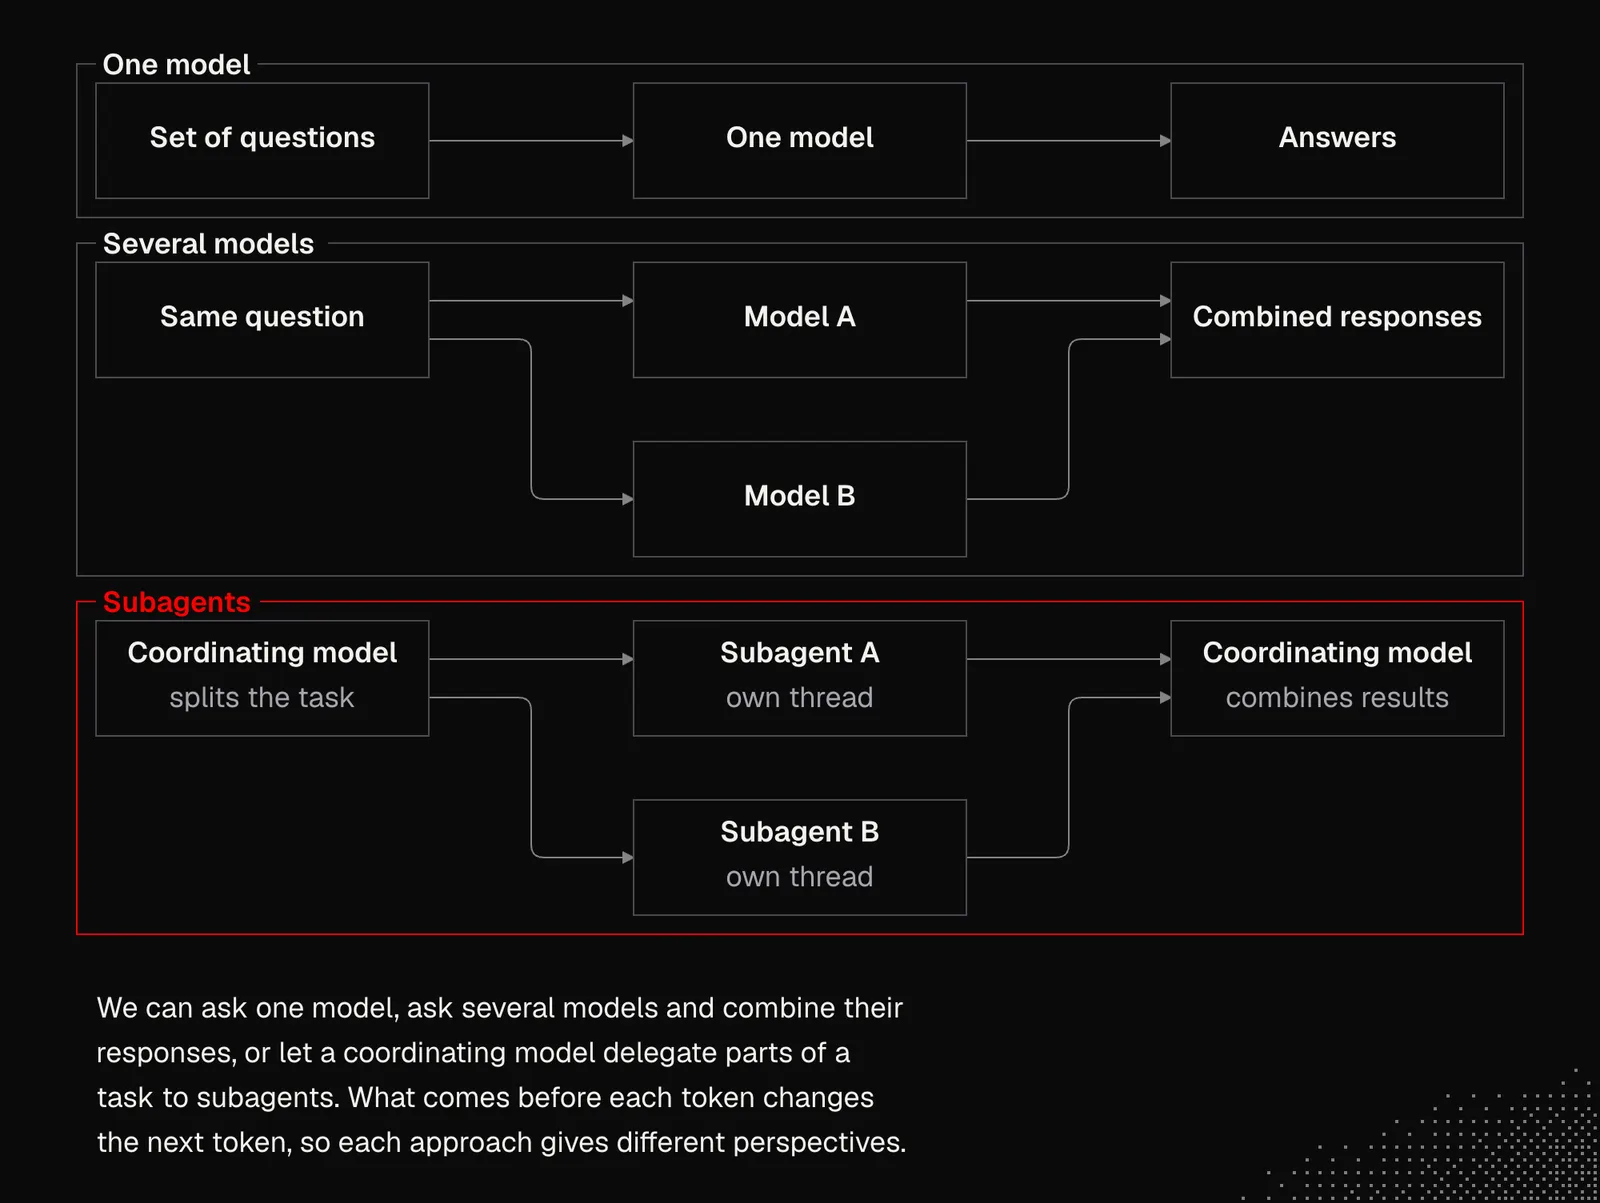
Different perspectives: We can ask AI a set of questions and wait for the results. We can also ask multiple models the same question and then combine the results. Another option is to ask a model to start multiple subagents (often as separate threads) and delegate different parts of a task to them. This takes advantage of the fact that models “think” by generating tokens, and that whatever precedes a token affects which token is generated next.
Run Ask models to send one question to several models at the same time and merge the answers into distinct perspectives. For subagents, open Subagents as tools: in my runs, one subagent per contract got 79 to 80 of 80 fields right, while a single agent holding all sixteen contracts got 75 to 79. Your results may vary.
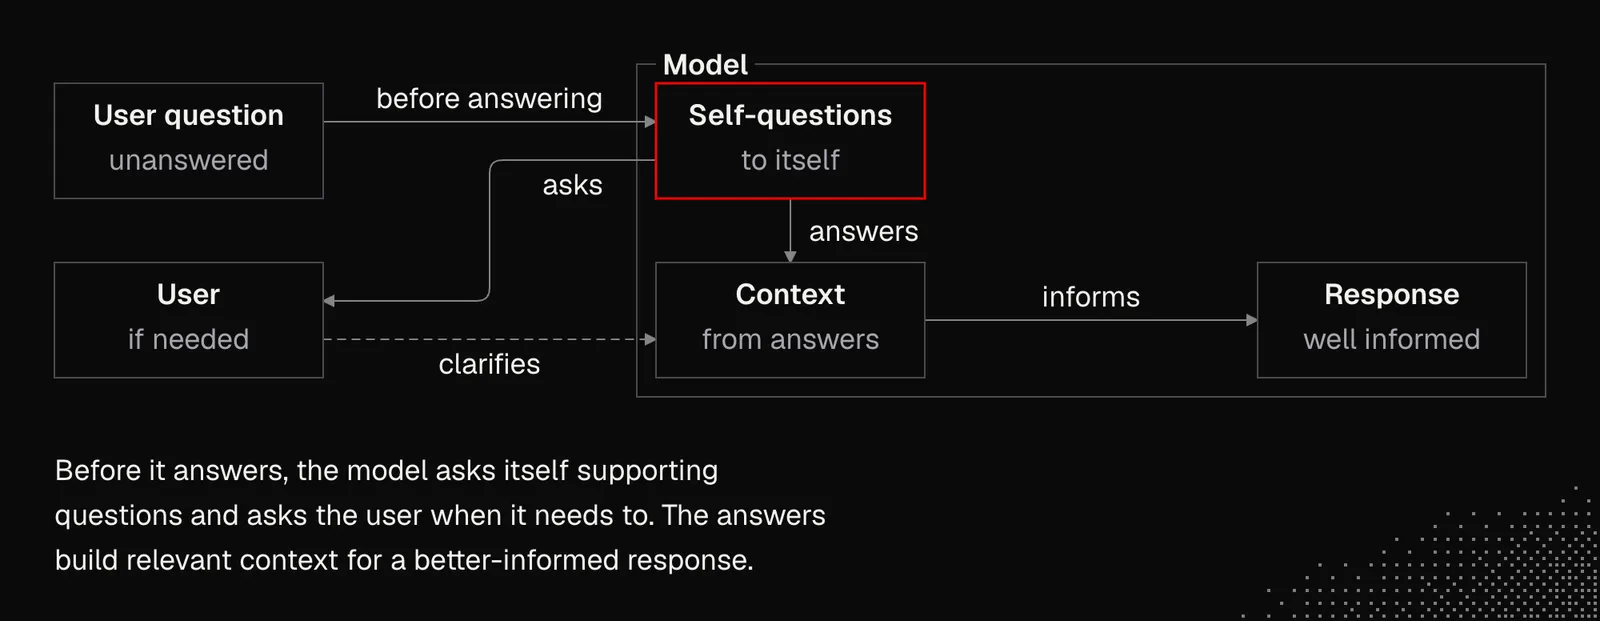
Self-querying: LLMs hold vast knowledge, but it often stays beyond the reach of the current interaction, namely the "working memory". We can ask a model a few questions before giving it the actual task. We may also ask a model to ask itself questions and then answer them to widen its own understanding of a topic.
Run Self-querying to answer one question twice: first directly, then after the model asks itself supporting questions. Read the questions it wrote, and compare how often each mode covers the key points over several runs.
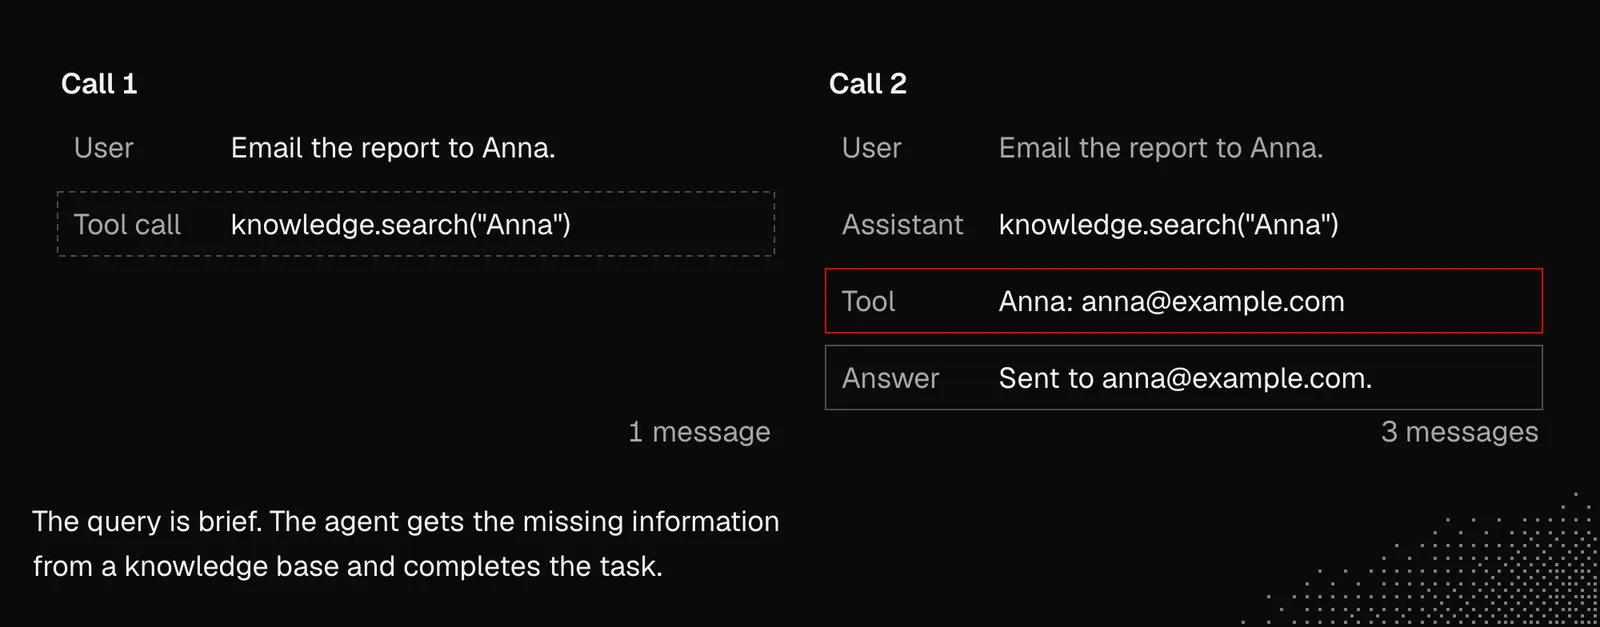
- Memory: Since every thread with an LLM starts from scratch, we can't expect even the most intelligent model to understand everything about us. Agentic memory remains an open problem, and we'll discuss various strategies to get the best possible results with it. For now, we just need to keep in mind that we need a way for an agent to access the required information to accomplish the task, even if that information wasn't included in our original request.
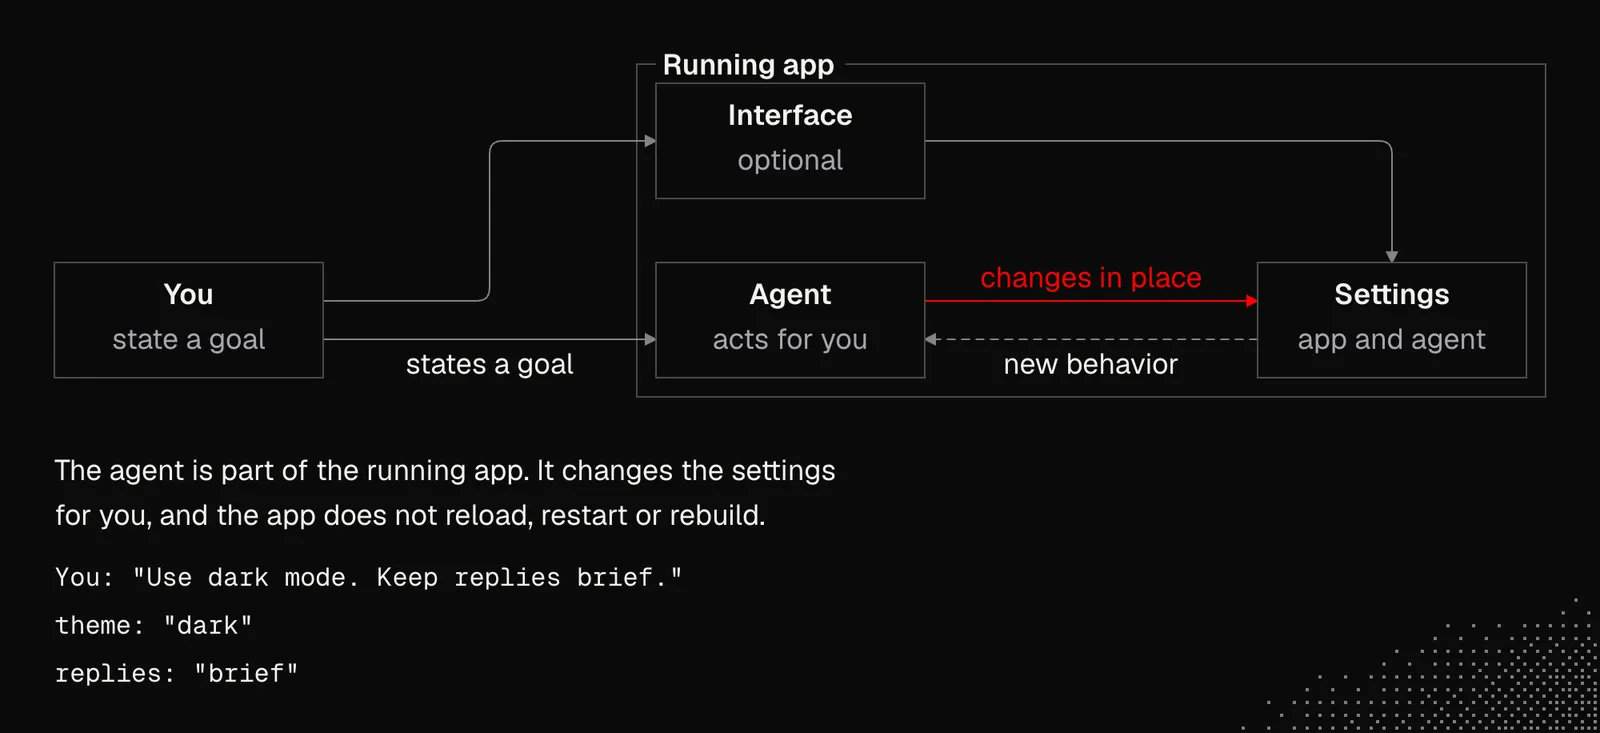
- Self-Management: There are signs that software is heading towards self-configuration or even self-evolution. Good examples are Pi and OpenCode 2, where agents can manage all the settings without having to reload the environment. This paradigm changes both the way we work with agents and the way we create software. In other words, agents have to become first-class citizens in software. And as users, we need to think about how agents can work on our behalf and manage themselves with minimal involvement from us.
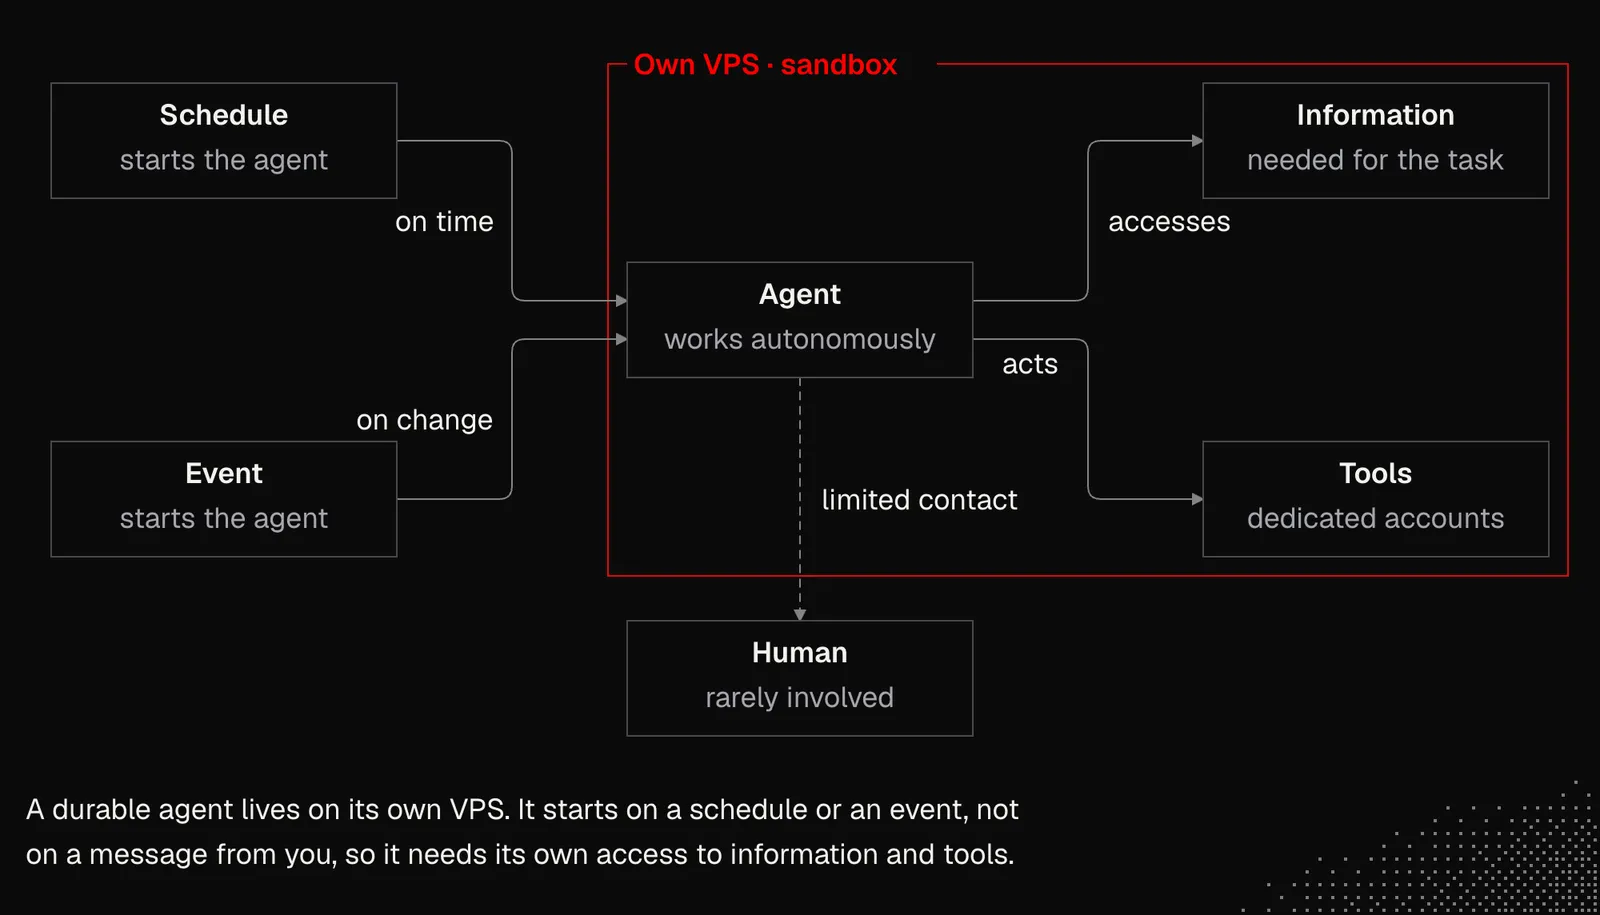
- Ambient, Durable Agents: We’re already familiar with working directly with agents. And while there’s still a lot we can improve about that, we’re quickly moving from local agents to remote agents that run on a schedule and respond to events. These agents are designed primarily to work autonomously, so their contact with humans is limited. We need to give them both a way to access necessary information and tools to interact with their environment safely and reliably. This often involves running agents in sandboxes, on their own VPS or PC, with dedicated accounts.
Takeaways
As I mentioned, this lesson should give you a broad, general overview of the core mechanics, and at this point, not everything needs to be perfectly clear. You can think of it as climbing a hill and looking around: you can see everything around you, just not in perfect detail.
The topics we covered today can be considered the core of generative AI. Models have progressed mostly through scaling rather than fundamental architectural changes, so this knowledge stays roughly the same.
As with any other technology we've encountered in our careers, it's worth diving into the details to get at least a basic understanding of what's going on under the hood. This lets us reason from first principles about working with agents or building them and makes it easier to tell what's just hype and what may hold actual value.